#ai generative media Startups & Tools
Discover the best ai generative media startups, tools, and products on SellWithBoost.
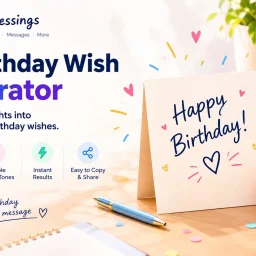
Charmblessings has built a free tool for a problem most people face at least once a year: a birthday is approaching and the right words won't come. The AI Birthday Wish Generator is aimed at anyone who needs a greeting quickly, whether that's a short note for a group chat, a sentimental line for a card, a romantic message for a partner, or a joke for a close friend. The site positions it as a practical shortcut for people who want a message that still sounds like them rather than a generic template. The tool's strongest idea is its emphasis on relationship. Users pick from a long list that spans family members, romantic partners, coworkers, bosses, teachers, and even pets, and the output is meant to reflect that connection. This matters because a birthday wish for a manager and one for a sister call for entirely different language, and the site treats that distinction as central rather than cosmetic. The tone selector extends this flexibility considerably. Options range from sentimental, joyful, and elegant to playful picks such as a Yoda voice, a drunken pirate, Shakespeare, or Snoop Dogg, which signals that the product is willing to be lighthearted as well as earnest. The form itself is straightforward. Users enter the recipient's name, optionally add their own name, select a relationship and tone, choose a length, and can include a special memory or detail that the generator can weave into the message. An optional emoji picker lets users add symbols to the final text. Results are presented for easy copying and sharing, which suits the stated use cases of WhatsApp messages and printed cards alike. The site also states that the service is free and requires no account, and that users can generate as many wishes as they like. Beyond that, the page offers no further pricing or business model details. Supporting the generator is a library of related content on the site, including anniversary wishes, belated birthday messages, and guides for nephews and daughters. These pages give users a place to browse for inspiration before generating a custom message, which adds depth to the offering.
Fashion e-commerce teams spend considerable resources on photoshoots to generate diverse product imagery—a costly bottleneck when brands need to showcase garments across multiple models, styles, and colorways. On-Model addresses this directly with AI infrastructure designed to transform static product photography into dynamic, on-model content at scale. The platform handles four core workflows: converting flat-lay images into on-model shots, generating packshot variations, recoloring garments, and swapping models across existing imagery. What distinguishes On-Model from broader AI image tools is its focus on garment preservation. The system maintains every stitch, seam, and pattern detail at pixel level—critical for fashion where product accuracy directly affects customer trust and return rates. The product accommodates high-volume operations through batch processing that handles thousands of images daily and integrates into existing workflows via REST API and TypeScript and Python SDKs. This infrastructure-first approach targets enterprise e-commerce operations rather than one-off content creation. The platform includes a library of 70+ AI models and allows brands to upload custom models to generate digital twins of their brand ambassadors. The customer roster spans 50+ brands across six countries, including both established labels like Pierre Cardin and Zalando alongside athletic and streetwear brands. This breadth demonstrates the technology works across different garment types and brand positioning. The business model remains undisclosed from the marketing materials. A free trial tier and demo booking option are available, but specific pricing is not detailed. This approach typically indicates usage-based billing or custom enterprise pricing, common for API-first platforms with variable throughput requirements. On-Model directly addresses a real pain point in fashion e-commerce: the gap between manual photoshoots and the demand for diverse visual content. Whether the garment preservation delivers on its promise and whether pricing aligns with cost savings versus traditional photography will determine its staying power in a crowded AI image space.
For product-based sellers overwhelmed by the friction of asset creation, a streamlined alternative has emerged. BlueVeta addresses a genuine pain point: the gap between having a product and having marketing collateral across every sales channel. Rather than juggling agencies, hiring photographers, waiting for designers, or manually prompted AI tools, the platform promises to compress months of production into minutes. The core premise is straightforward but ambitious. Users upload a single product photo—even a casual phone shot will do—and receive 25 or more finished assets: professional studio renderings, lifestyle compositions, short-form video, and platform-specific copy ready to deploy across Instagram, TikTok, Amazon, email, and 16 additional channels. The output spans 10 languages, addressing multi-regional sellers directly. No additional editing is required; assets ship pre-sized for their intended destination. What distinguishes the offering is its refusal of the subscription model. Rather than locking users into recurring charges, BlueVeta prices individual packs at $9.99, with bundles available at better rates. The business model eliminates a major adoption barrier for one-off campaigns or small sellers testing the waters. A free demo dashboard lets prospects explore real output from actual products before committing. The product positions itself deliberately against two alternatives: the traditional agency workflow (expensive, slow, relationship-dependent) and the current chaos of single-task AI tools (fragmented, inconsistent, lacking continuity). To that end, BlueVeta introduces brand memory—a learning mechanism that absorbs information from user uploads, explicit feedback, edits, and even website content. The system claims to progressively internalize voice, visual style, and audience preferences, so repeated use improves output relevance and brand coherence over time. The founder's framing emphasizes simplicity: one upload triggers 18 automated steps behind the scenes, handling everything from image generation to copywriting to platform adaptation. The service covers diverse product categories—from food and beauty to electronics and home goods—suggesting broad applicability. The core risk is inherent to the category: AI-generated lifestyle photography and copy carry consistency and authenticity questions that remain unresolved across the industry. Whether algorithmically produced scenes and messaging satisfy demanding sellers, particularly those competing on brand differentiation rather than price, remains an open question. Nevertheless, the product's combination of speed, accessibility, and pay-per-use pricing positions it squarely where small and mid-sized brands currently spend their time and money.
Creators and small brands managing visual content face a fragmented workflow: generate images on one platform, edit them on another, then find a separate tool for video creation. Uyo consolidates these tasks into a single browser workspace designed specifically for creators who need fast turnarounds without compromising on customization. The platform generates images from text prompts, then lets users refine them through integrated editing tools including upscaling, background removal, and reference photo adjustments. Users can also transform static images into short videos, either by providing a new text description or by letting the AI animate existing visuals. This flexibility lets creators iterate quickly, moving from concept to finished asset without switching applications. What distinguishes Uyo is its focus on transparency and control. The interface displays estimated credit costs before generation, letting users make informed decisions about their spending. The workspace automatically saves all tasks and results in a personal "My Creations" library, eliminating the friction of hunting through generated files or losing track of which prompt produced which output. This organizational approach directly addresses the chaos that often accompanies bulk content creation. The platform curates a collection of reference images and videos across categories like portraits, landscapes, illustrated characters, and everyday scenes. Each reference includes the prompt used to create it, allowing users to study techniques and adapt them for their own projects. This gallery serves as both inspiration and a learning resource, especially valuable for creators without formal training in AI prompt engineering. Uyo supports both English and Chinese interfaces, signaling an intention to serve international markets. Access requires an account and credits purchased in one-time packs, positioning the tool as a consumption-based service rather than a subscription model. For small businesses and independent creators, this approach offers flexibility in budget allocation across multiple platforms. The combination of generation, editing, and video creation in one cohesive environment—paired with deliberate design choices around cost visibility and result organization—positions Uyo for creators tired of patchwork workflows. Whether users prioritize speed or fine-grained control, the platform attempts to accommodate both.
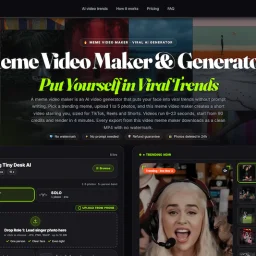
Meme culture thrives on participation and remixing, but most viral formats require technical editing skills or specialized tools. This new service strips away that friction by automating the core mechanics of one of TikTok's most durable audio trends: the "Outstanding" desk-concert parody inspired by NPR's Tiny Desk series. The product works with elegant simplicity. Users upload between one and five photographs—of themselves, friends, or anyone else willing to be part of a video—and the software places each face into a corresponding position within the meme template: lead vocalist, keyboardist, backing vocalists (two positions), or saxophonist. The system then renders a fresh 19-second vertical video in 720p, framed and edited to match the original's four-shot structure and cramped office setting. Crucially, the video ships without audio, requiring users to add the meme's iconic backing track directly on TikTok—a design choice that sidesteps licensing complexity while keeping the creation workflow focused. What distinguishes this approach is its commitment to reducing friction. There is no account creation, no AI prompt engineering, no layer of post-production editing. A user selects seats, uploads photos, pays $8.99 once, and receives a render. The experience is transactional and transparent: no recurring charges, no data harvesting beyond the immediate render cycle, and explicit commitments to delete uploaded photos within a day. Empty seats automatically populate with fictional musicians, so a user can generate a complete video with just a single photo. The pricing model mirrors the service's ethos. At $8.99 per video, the cost sits well below the friction threshold that would deter casual participation, while clearly establishing a commercial model rather than a free-tier trap. The one-time payment structure removes the psychological friction of ongoing subscriptions. This targets a specific but sizable audience: TikTok creators and meme enthusiasts who want to participate in established viral formats without learning new tools. It succeeds by doing one thing exceptionally well—turning a meme template into a personalization platform—rather than overextending into editing suites or AI-generated content sprawl. The product respects both the mechanics of meme culture and the constraints of its platform.
Viral meme replication typically demands either technical skill with video editing software or expensive creator services. Rumpelstiltskin AI solves this by reducing the barrier to near zero: upload a photo or two, pay $8.99, and receive a finished 15-second video ready to post. The product targets TikTok creators and social media users who want to participate in meme trends without learning editing timelines or committing to subscriptions. It operates on a template model, inserting user faces into a pre-shot sequence of the "tip toeing in my Jordans" meme. This is not face-swapping. The company films eight distinct shots with physical sets and actors, then composites the user's face into five to seven of those cuts depending on role selection. The remaining shots stay as original footage, typically showing hands, feet, or angles where face insertion would be unnecessary or uncanny. What distinguishes this product is its refusal of friction. There is no account creation, no prompt engineering, no timeline scrubbing. The user selects one or two photos, chooses a role (the imp, the girl, or both), clicks "cast," and the rendering begins. The company handles casting, filming, and compositing without asking for granular controls. The output is a silent MP4, intentionally design-limited so that users must attach audio on TikTok itself, which is where the meme lives. The pricing model reinforces this simplicity: $8.99 per video, no recurring charges, no cancellation mechanics. The company demonstrates transparency about its methods. The website explicitly states which shots are newly filmed and which are always pre-made footage, differentiating itself from services that promise total customization. Uploads are deleted 24 hours after rendering, and videos are private by default. The acceptable use policy requires confirmation that all people in uploaded photos are adults who consented and are not public figures, which attempts to preempt the most obvious legal and ethical misuses. The fixed edit structure is both a feature and a limitation. The 8-shot sequence never varies; cuts always land on the beat. This predictability means faster rendering and consistent output quality, but it also means zero creative deviation. Users cannot request different choreography, camera angles, or scene variations. At $8.99 for a one-time creation, the product is positioned as an impulse purchase rather than a production tool. It targets participants in trend cycles rather than professional creators, and it prices accordingly.
A trend tool for couples wanting participatory viral content, Zombie Couple Video generates fifteen-second vertical clips from two portraits for $8.99 per video. The creator positions this around the autumn 2026 zombie couple aesthetic—a scenario where one partner becomes undead in a rain-soaked standoff while the other, armed with a rifle, cannot bring themselves to shoot. The narrative resolves with a hard cut to a sunlit memory of the pair embracing. The product's strength lies in radical simplicity. There is no app to download, no account to create, no timeline to navigate. Users upload two images, confirm consent and age verification, and pay directly through Stripe. The entire process treats the output as a finished asset: the 720p MP4 arrives with music and sound effects already mixed in, formatted at 9:16 for mobile phone screens and ready to share immediately. The AI handles the substantive creative work. It transforms one photo into a zombie version, stages the survival scenario, choreographs the climactic jump, and cuts to the memory. The rendering happens server-side while users wait or step away. The examples shown—rendered from fictional test faces and presented unedited—suggest consistent visual coherence across the pipeline. Privacy and consent are explicit commitments. The founder emphasizes that all subjects must be adults, must consent to participation, and cannot be celebrities or public figures. Uploaded photos are deleted within 24 hours regardless of whether rendering succeeds. This directly addresses tensions around AI image generation and consent that plague many generative tools. The business model is transparent: each video costs eight dollars ninety-nine cents, charged once, with no recurring subscriptions or account balances. There are no credits to manage, no pressure to pre-purchase batches, no friction between the intention to create and the act of paying. What distinguishes this product is not the AI video generation capability itself but its ruthlessly focused application to a specific, trending scenario. The creator recognized a cultural moment and built exactly one thing to serve it well: an unburdened tool that removes friction between impulse and artifact. The stripped-down scope is deliberate. A user enters with two photos and a social media intention. They leave with a ready-to-post clip in under two minutes. The inherent risk is trend decay. The zombie couple aesthetic may fade as quickly as it rose. But the execution—the consent frameworks, the privacy commitments, the friction-free interface—establishes a working template that could theoretically adapt to other fleeting relationship video trends if cultural moments demand it.
Capitalizing on a viral dembow moment that swept through Latin media in October 2026, this tool converts a single selfie into a 12-second vertical video of the user lip-synced to a freestyle verse that generated tens of millions of views across platforms. The service addresses a specific use case: enabling social media users to participate in a cultural trend without requiring video production skills, equipment, or account creation. The product's core strength is its radical simplicity. Users upload one clear facial photograph, verify they own the likeness, and pay $8.99 for a rendered MP4. No editing interface, no customization prompts, no strategic decisions beyond image selection. The output arrives as a mobile-ready vertical clip with lip-sync timing calibrated to the beat. The silent video design—users add audio when posting—keeps the production pipeline focused and the tool's scope deliberately narrow. Several design choices reveal intentional restraint. Uploaded images disappear within 24 hours, treating data minimization as a feature rather than a policy footnote. The service operates without accounts or subscriptions, eliminating authentication friction and the pressure to grow monthly active users. The creator frames this as an unofficial fan tool with no artist affiliation, setting clear expectations while sidestepping brand partnership complications. The one-time payment model at $8.99 per video signals the creators understand their own market constraints. This is a trend-capture product built for a moment, not a platform engineered for perpetual engagement. The business structure treats each video as a discrete transaction: pay once, receive an asset, the relationship ends. Users retain no profile, no library, no reason to return except to make another video during the trend's active window. The limiting factor is self-evident: viral moments in music have finite lifespans. The tool's entire value depends on sustained participation in the Bulin 47 trend. Should interest fade, so does relevance. The product makes no attempt to extend utility beyond the specific cultural moment it targets, which appears intentional rather than an oversight. This focus, while commercially risky long-term, makes the offering honest about what it is and what it actually does.
Creating viral social media content typically requires either significant technical skills or expensive tools. This AI video generator addresses that friction by packaging a single trending format into an extremely focused product that requires nothing more than two photos and $8.99. The core service transforms a pair of user-supplied images into 15-second TikTok videos matching the "Hotel Lobby" trend, where one photo raps into a hanging microphone while the other dances in an orange booth. The template is pre-configured, meaning users skip the usual AI video workflow of writing prompts, selecting models, or tweaking parameters. The service handles lip-syncing automatically to the established trend sound, and the output arrives pre-formatted in 720p MP4 at 16:9 aspect ratio—ready to post directly. What distinguishes this product is its deliberate simplicity. Most AI video tools force users to learn their systems, experiment with settings, and make creative decisions. This one does the opposite: it eliminates options. There is no account signup requirement, no creative customization, no editing phase. Users select two images, confirm they have permission to use them, and submit payment. The philosophy of constraint-driven design shows throughout. The product even includes a feature to swap performer positions before payment, eliminating a common source of regret with one-way transactions. Privacy receives explicit attention in the product design. The service deletes photos within 24 hours, whether the generation succeeds or fails. The terms explicitly address consent, prohibiting use of images containing minors, celebrities, or public figures—a meaningful guardrail against the misuse that plagues many generative tools. The pricing structure removes subscription friction entirely. At $8.99 per video with no recurring charges, the transaction is transparent and one-off. Failed generations automatically refund credits, eliminating the anxiety that often surrounds experimental features. The target user is clear: social media creators who want to participate in a specific trend without spending hours learning software or acquiring new skills. This narrowness is intentional. The product refuses the temptation to become a general AI video tool, instead excelling at a single outcome. That focus, combined with the frictionless workflow and transparent pricing, creates a compelling value proposition for anyone who sees the trend and wants in without the complexity.
The appeal of meme culture and viral moments lies partly in their unpredictability—watching an unexpected person inserted into a familiar scene creates comedy through surprise and recognition. A social media creator seeking to tap into this trend faces a barrier: producing convincing video content requires either professional equipment and editing skills, or access to expensive AI tools that demand technical knowledge and ongoing subscriptions. RapZap addresses this friction by packaging AI video generation into a strictly bounded, template-based service. The product targets people who want to generate short performance clips for social sharing without building skills or maintaining an account. Users select from five predefined scenarios—a hotel lobby duet, a solo rap verse, a zombie love story, a barn dance meme recreation, and a desk concert—add between one and five face-forward photos, pay 8.99 dollars once, and receive a finished 720p MP4 ready for TikTok, Instagram Reels, or YouTube Shorts. The design emphasizes simplicity over customization. No prompting interface exists; no editing stage comes after rendering; no ongoing relationship with the platform is required. This constraint-based approach avoids the choice paralysis that plagues general-purpose AI tools while keeping friction minimal. Photos are deleted within 24 hours of processing, addressing privacy concerns without requiring lengthy data retention policies. The underlying technology stacks image-based face reconstruction with video generation to animate body movement and mouth synchronization. The quality depends heavily on input—the site explicitly recommends sharp, forward-facing shots with one person or animal per photo—but real examples from the live pipeline demonstrate output suitable for social sharing at the specified resolution and frame rates. Financially, the model is straightforward: 8.99 dollars per video with no recurring charges or hidden account requirements. This positions RapZap as an impulse purchase for casual creators rather than a platform requiring ongoing commitment. The one-time transaction removes decision friction for users curious enough to try but unwilling to subscribe. The service succeeds by acknowledging what it is not. It rejects the ambition of general AI video tools in favor of nailing a narrow use case: turning ordinary photos into recognizable meme variations that work at short-form video scale. That focused scope is its strength. For someone wanting to make their friend appear in a viral moment without learning video production, RapZap delivers exactly what is promised.
Viral short-form video creation has historically required either video editing skills or AI prompt fluency—two barriers that keep most people from participating in trending meme formats. This service eliminates both by packaging trending video templates with face-insertion AI, letting users simply upload photos and receive finished MP4s optimized for TikTok, Instagram Reels, and YouTube Shorts. The product targets social media users who want to capitalize on viral trends without learning Adobe Premiere or mastering AI prompting. The pitch is straightforward: pick a trending template, upload between one and five photos, and the system generates a 15-second video with the user's face composited into the choreography or scenario. Every video exports watermark-free in vertical 9:16 format. What distinguishes this offering from broader AI video generation tools is its template-first design. Rather than asking users to describe what they want, the service presents curated trending formats—currently 17 active templates spanning dance routines, music duets, comedy scenarios, sports moments, and cinematic sequences. This constraint is actually a strength; it trades unlimited creative freedom for reliability and speed. A template-based approach also naturally produces scroll-stopping content because the templates themselves are already proven viral hits. The execution details suggest thoughtful product design. Photo upload works via traditional browser selection or QR code scanning from mobile, acknowledging that users often have images on their phones. The service provides specific guidance on photo composition—front-facing, clear lighting, waist-up framing—to optimize AI face-insertion results. Render time is quoted at four minutes, competitive for real-time content creation. The privacy model deletes uploaded photos after 24 hours, addressing a legitimate concern about personal image data. The business model operates on a credit system, with a single video consuming 90 credits, though explicit pricing is not disclosed on the available text. The company emphasizes a refund guarantee, reducing perceived risk for first-time users evaluating the service. The main limitation is format rigidity. Users don't generate videos; they participate in predetermined templates. This works perfectly for trend-chasing and social proof but won't appeal to creators wanting original concepts. For the intended audience—people who want to be seen in trending formats without friction—the constraint is a feature, not a bug.
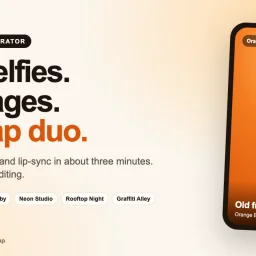
Generating personalized music videos has traditionally required significant creative effort, specialized software, and often, musical ability. AI Rap Video addresses this friction by automating the entire creative pipeline—from lyric writing through beat production to video generation—in a single, straightforward workflow. The product targets users seeking shareable entertainment content with friends or family. The use cases span birthday tributes to meme remakes, appealing to anyone wanting novelty content without the skill barrier. The core appeal is accessibility: upload two selfies, select a backdrop, and receive a fully realized music video in approximately three minutes. Several capabilities distinguish this offering. The AI generates original lyrics and beats tailored to each generation, rather than relaying stock templates. The product offers six distinct stage aesthetics—ranging from an Orange Booth to Rooftop Night to Graffiti Alley—allowing users to customize the visual context. The generated videos feature lip-synced performances that map the AI vocals to the uploaded faces, creating a cohesive illusion of live performance. The output is delivered in vertical format at 720p resolution without watermarks. The platform incorporates meaningful safeguards. Generated videos automatically delete after seven days, and the creator explicitly states user photos are not used for AI model training. Failed generations trigger automatic credit refunds, reducing financial friction. Users can optionally specify topics for the AI lyrics—birthday shout-outs, relationship origins, lighthearted competition themes—or let the system choose. The business model relies on a credit system, with songs priced at 10 credits. The company does not publicly disclose credit-to-dollar conversion rates on the provided materials, making the true cost per video unclear to prospective users without visiting the full site. This opacity is a minor friction point, though the auto-refund policy and privacy commitments address legitimate user concerns around trust. The product execution is polished. The sample outputs shown across all six stages demonstrate consistent video quality and convincing facial animation. The interface design guides users through a logical progression—photo selection, stage choice, optional customization, then generation. AI Rap Video succeeds in lowering the barrier to music video creation. For users seeking entertaining, shareable content without creative skill, the streamlined workflow delivers clear value. The combination of AI-driven content generation, multiple aesthetic options, and user-protective policies positions it as a viable entry point to video creation for casual audiences.
Consolidating creative workflows into a single platform addresses a genuine frustration for digital creators. MikeSullyTools bundles tools for photo editing, video processing, AI-powered image generation, PDF conversion, and marketing content creation into a unified browser-based hub, eliminating the context switching that derails productivity. The product targets content creators, digital marketers, and small business owners who regularly move between specialized applications. Rather than maintaining separate subscriptions for photo enhancement, video cleanup, AI generation, and document work, creators access these capabilities from one login. The platform distinguishes itself through breadth of functionality. Beyond core media tools like AI Photo Studio and AI Video Studio, it integrates business-focused features including rate card calculators, UTM and QR code builders, campaign concept generation, and brand deal brief templates. The inclusion of a voiceover recorder and caption and hook generator reflects an understanding of modern creator workflows. A Creator Media Kit Generator and Brand Deal Brief Builder position the tool as serving not just production but the business side of content work. The feature set reveals intentional scope decisions. The platform handles foundational tasks—quick photo and video fixes, AI image generation, PDF-to-Word conversion—rather than competing on professional-grade editing depth. This positioning suits creators seeking efficiency over specialized control. The addition of marketing tools like Campaign Concept Studio and Creator Planner suggests the founders recognize that creators spend significant time on strategy and business development, not just asset creation. MikeSullyTools operates a freemium model with paid member accounts restoring or replenishing credits. The specific tools available to free versus paid tiers are not detailed in available materials, though the platform offers complimentary access to essentials like PDF conversion, voiceover recording, and UTM building. The brand maintains presence on directories including Trustpilot, MarketingDB, SumoDir, and Founder.best, signaling efforts toward marketplace credibility. The platform supports standard authentication including Google sign-in and optional two-factor authentication, indicating attention to account security for creators managing multiple projects. For creators fatigued by tool fragmentation, MikeSullyTools presents a legitimate solution to reduce friction in daily workflows. Its strength lies not in pioneering technology but in thoughtful consolidation of established capabilities around real creator pain points.
Artificial intelligence promises to democratize technical skills, but the gap between aspiration and execution remains wide for many entrepreneurs and creators. Volnyn addresses this friction by removing the need for coding or design expertise when building digital products. The platform positions itself as both a website builder and broader AI workspace, enabling users to construct websites and applications through conversational prompts rather than traditional development workflows. This shift from interface-based design to natural language commands represents a meaningful departure from existing no-code tools, which typically still require users to think in terms of components and layouts. The founder's vision centers on eliminating technical barriers for talented people with ideas but without the skills to execute them. The company achieves this through the combination of AI capabilities with no-code infrastructure, allowing users to automate workflows, build apps, and launch websites through simple text prompts. For solopreneurs, small business owners, and individuals exploring ideas without development resources, this reduces both the learning curve and the time investment required to validate concepts. Volnyn targets users across a spectrum: from those automating repetitive business processes to entrepreneurs prototyping minimum viable products to non-technical professionals seeking to build applications without hiring developers. The emphasis on prompt-based building prioritizes accessibility over granular control—a trade-off that favors faster iteration but limits customization for users with specific technical requirements. The website content provides minimal detail about specific features, pricing models, or competitive differentiation beyond the core value proposition. No information is publicly stated regarding cost structure, feature tiers, or deployment options. This absence makes it difficult to assess whether the product targets bootstrapped founders, small businesses, or enterprises, or if it caters to all segments equally. For anyone skeptical of no-code tools' capabilities, Volnyn's execution will matter more than its positioning. The real test lies in whether natural language prompts genuinely translate to functional, production-ready applications or if they produce templates requiring significant manual refinement—a common limitation in AI-assisted builders. Until more detailed feature documentation becomes available, potential users should evaluate whether the tool's abstraction level matches their project requirements.
Fragmented video creation workflows waste hours. Creators typically bounce between text-to-video generators, image tools, editing software, and platform-specific uploaders before their content reaches audiences. ReelMint consolidates this scattered stack into a single workspace designed around the complete journey from concept to publication. The platform tackles a genuine friction point in short-form content production. Rather than building yet another AI video generator, ReelMint adds a multiplier: once a video exists, one click distributes it across TikTok, YouTube, Instagram, Facebook, and X with custom captions for each platform. The founder describes this directly as motivation—the realization that posting consumed as much time as creation itself. The feature set reflects that integrated philosophy. A user describes an idea, selects an AI model (currently including Seedance, Kling, and Veo), and receives a video with voiceover, music, and captions before confirming the cost. The multi-scene builder lets creators assemble AI-generated clips into longer films while maintaining consistent character appearances across scenes. Mint Moments accepts up to 15 photos and auto-edits them into a scored vertical film. Mint Ads takes a website URL and generates a narrated commercial from its actual content and design. For scheduling, Bot Studio handles recurring video generation and cross-posting on defined intervals. A conversational interface called Minty provides voice control over these features. Where ReelMint differentiates itself most is transparency and accessibility. Credit costs display before generation, not after surprise charges. The pricing floor sits at $9.99 monthly, and the platform offers 27 free-to-generate templates immediately. All plans unlock every AI model without artificial restrictions—a pricing structure that rewards exploration over gatekeeping. The livestream feature, Mint Live, extends the model to real-time content by putting AI characters directly on air within YouTube or TikTok LIVE streams, though implementation details remain opaque in available materials. The core value proposition is straightforward: reduce the hours spent orchestrating tools down to typing a prompt and clicking publish. For content operators managing multiple channels, marketers needing rapid ad iteration, or creators maximizing output without hiring editors, the consolidated workflow and multi-platform posting address a documented pain point. Whether the execution matches the promise would require hands-on testing beyond these promotional materials.
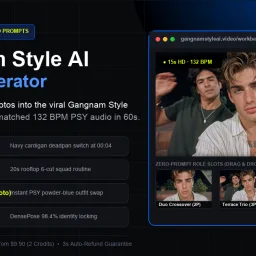
Viral dance videos have become a cultural phenomenon, but creating professional-quality versions requires technical skills most people lack. This AI video generator tackles that barrier by letting users transform 1-3 portrait photos into synced 15-second Gangnam Style dance videos without writing a single text prompt. The target audience spans casual creators who want shareable content quickly, social media enthusiasts looking for a novel way to feature photos, and anyone nostalgic for the 2012 phenomenon seeking to recreate it with modern faces. What distinguishes this tool is its singular focus. Rather than being a generalist video generator, it commits entirely to one dance and three preset choreography templates, eliminating decision paralysis. Users select between the Blue Tux Solo, Street Duo, or Terrace Trio formation, upload their photos to marked role slots, and receive an MP4 in under a minute. The 132 BPM audio syncing to PSY's original track happens automatically, and the platform claims 98.4% facial accuracy across fast-moving choreography, a technical claim that matters given how video synthesis typically fails on rapid motion. The product supports both landscape (16:9) and portrait (9:16) aspect ratios, accommodating TikTok creators alongside desktop viewers. Users can generate in either 720p or 1080p Full HD. Photo requirements are practical: clear, front-facing waist-up portraits with natural lighting, which aligns with smartphone capabilities. The business model prioritizes simplicity and trust. Pricing starts at $9.90 for a single 720p generation, with 1080p available through a credit system. There is no subscription; each generation is a one-time purchase. The platform offers a 3-second auto-refund guarantee and purges uploaded photos after 24 hours, directly addressing privacy concerns that plague photo-based AI tools. The core limitation doubles as the core strength: this solves a highly specific problem for a specific trend. It cannot serve users wanting unlimited choreography variety or custom music. For the narrow use case it addresses, however, the no-prompt interface, preset role system, and automatic audio syncing eliminate friction between idea and output. The one-time pricing without subscriptions positions it as a novelty purchase rather than a recurring service, which suits its entertainment-focused positioning.
Video content creation typically demands technical skills. Beau Is Afraid AI Video Generator removes that barrier by letting users create a specific, shareable video in minutes—inserting themselves and a friend into the film's infamous bathtub scene. The product targets casual creators who want viral-worthy material without learning editing software. The core appeal rests on simplicity and social mechanics. Users upload two portraits, assign one person to the bathtub and another to fall from above, and generate the video instantly. No writing prompts, no reference videos to find, no timeline to adjust. The product handles the heavy lifting while users focus on casting and sharing. The two-photo interface makes the interaction between people central to the content, transforming what could be a generic face-swap into a narrative moment. The bathtub scene itself is the competitive advantage. By anchoring to a specific viral moment from cinema, the product trades customization for immediate recognizability. Users don't design their own scenes; they populate an existing one. This constraint actually accelerates creation and ensures consistent quality, since the underlying footage is predetermined. The role-reversal feature allows multiple generations from the same two photos, extending the novelty. Distribution is built into the product's DNA. Videos are designed for group chats and social sharing, with download functionality that makes distribution frictionless. The founder emphasizes entertainment as social—the act of assigning roles within a friend group becomes part of the experience, not just the finished video. The product philosophy centers on accessibility over flexibility. There are no customization options mentioned: no scene variants, no prompt engineering, no timeline editing. This narrowness is intentional, enabling the straightforward experience the founder describes. It's a trade-off that works if the bathtub scene resonates with users; it becomes a limiting factor if that novelty fades. The business model is not detailed in available materials, making full assessment difficult. What's clear is that the product succeeds if it becomes the default way a specific demographic creates shareable content around this meme. The viral potential hinges on network effects: each shared video demonstrates to others that generation is instant and accessible. The entire value proposition depends on whether that particular scene remains culturally relevant enough to drive repeated use.
Game developers frequently face a bottleneck when prototyping new projects: creating animation assets requires specialized pixel art skills, expensive freelancers, or months of learning. SpriteGen addresses this constraint by automating sprite sheet generation through a natural language interface. The service works straightforwardly. Users describe a character and action in plain English—such as "a knight swinging a sword"—then select a perspective, visual style, and animation type. The system generates a complete sprite sheet within minutes, complete with transparent backgrounds and evenly spaced frames. Before downloading, creators watch a live animation preview, seeing exactly how their character moves across the generated frames. This preview-first workflow removes guesswork and enables quick iteration without exporting incomplete work. What distinguishes SpriteGen is its combination of speed and usability. The browser-based interface flattens the typical asset creation pipeline. Rather than learning animation rigs or commissioning custom work, solo developers and small teams produce placeholder or final assets on demand. The output formats—PNG at various resolutions, from 32-pixel cells to HD—integrate directly into common game engines, eliminating post-processing steps. The product demonstrates thoughtful design choices in its scope. The preset library curates successful examples showing both the tool's capabilities and what effective prompts look like. Animation types cover essential game actions: idle, walk, run, jump, attack, hurt, and death, enabling developers to generate sprites for core gameplay loops. The style selection—16-bit, retro handheld, cute, cozy farm—appeals to creators targeting specific aesthetic directions. Pricing follows a consumption model: four credits per sprite sheet with no mandatory subscription. The Starter plan costs $16 monthly for 300 credits, supporting roughly 75 sprites per month. This structure suits prototyping workflows where demand fluctuates, though heavy production users would need higher tiers. SpriteGen occupies a clear niche in game asset creation, reducing friction for developers lacking art skills but needing functional animation assets. It trades design flexibility for speed and accessibility, a tradeoff that suits rapid prototyping and smaller projects over bespoke visual identity work. For solo developers and small studios exploring character ideas, the tool delivers measurable value.
Event planning typically unfolds across a frustrating divide: hosts envision an aesthetic in their minds, but vendors and planners struggle to translate that vision into concrete orders and purchases. Eventscape.ai addresses this friction directly by converting text descriptions into photorealistic room and table designs within minutes. The tool's core strength lies in collapsing the gap between concept and execution. A user describes an event in natural language—"anniversary dinner for 16, burgundy and gold, candlelight"—and receives a photorealistic visualization in two to three minutes. This removes the traditional bottleneck where Pinterest boards and mood boards never quite match the intended outcome, and where planners waste hours building these materials manually. What distinguishes the product is the Designer Brief accompanying each visualization. Rather than stopping at aesthetics, the tool generates an itemized shopping list that breaks down every element—linens, vases, candles—with quantities calibrated to the specific guest count. This transforms the service from a visualization tool into a planning and procurement asset. A user can immediately share this brief with vendors or use it for self-shopping, eliminating the manual work of building lists from scratch. The product targets event hosts and planners seeking to see their vision materialized before committing to purchases. This is particularly valuable for occasions where budget and aesthetic alignment matter significantly, such as weddings, anniversaries, and milestone celebrations. The founder's background running a boutique event studio suggests the product emerges from direct experience with these operational pain points. Regarding business model, the product offers the first design free, lowering the barrier to entry and allowing users to experience the core value proposition before any financial commitment. Beyond this freemium hook, no pricing structure is publicly disclosed, suggesting either an early-stage approach or intentional simplicity focused on conversion through first-use value. The offering is deliberately narrow in scope. Rather than attempting to solve every aspect of event planning, the tool concentrates on the visualization-to-procurement pipeline, where friction creates the most operational waste for planners and hosts alike.
Chrome extension users managing affiliate marketing campaigns face a friction point: turning a promising product deal into publishable content across multiple platforms demands time-consuming manual work. The process typically involves extracting product details, writing promotional copy, appending affiliate tags, and then reformatting the same content for different platforms like Telegram, WhatsApp, Reddit, X, and Facebook. Deals Copier addresses this by automating the workflow with a single-click extraction and AI-assisted post generation. The tool targets affiliate marketers and deal aggregators who distribute across multiple channels. Rather than building yet another dashboard, the creator embedded the functionality directly into users' browsing experience. When a user encounters a product on Amazon, eBay, Walmart, Woot, or Flipkart—across 30 regional sites—they trigger the extraction from the extension popup. The system captures pricing data, discounts, bank offers, and product images without requiring manual input. What distinguishes this approach is its focus on privacy and user control. Deal data extraction runs entirely in the browser, never routing through company servers. This design choice reduces latency and eliminates data transmission concerns. Users can preview affiliate links before saving them, with support for multiple affiliate networks including Amazon Associates, eBay Partner Network, and Rakuten. The AI component handles title shortening, pitch writing, and translation into twelve languages. Rather than replacing manual creativity, the tool handles the mechanical work—formatting text for platform constraints, creating image collages, or generating square carousel videos. Users toggle which features they want for each deal. The commercial structure operates as a freemium model. The free tier provides ten monthly AI-powered writing requests, sufficient for users experimenting with the workflow. A Pro plan unlocks unlimited AI writing and translation services. This pricing approach avoids forcing users to commit to a subscription before understanding the product's fit for their workflow. The extension supports regional Amazon marketplaces (22 total) alongside other storefronts, recognizing that affiliate marketers operate across geographies. Built-in compliance features include optional affiliate disclosure tags and price disclaimer appended to exports. For affiliate marketers drowning in formatting overhead, the value proposition centers on reclaiming time. The tool's strength lies not in discovering deals—users retain that responsibility—but in mechanizing the post creation, allowing rapid distribution once a worthwhile deal is identified. Whether the time savings justify adoption depends on deal volume and platform diversity in individual workflows.