@fuck.it
Email privacy has become an afterthought at mainstream providers, which treat inboxes as data sources to be mined for ad...
Categories
Best Transcription Startups & Tools
Turn audio or video into written text.
Recently Listed
7 launches
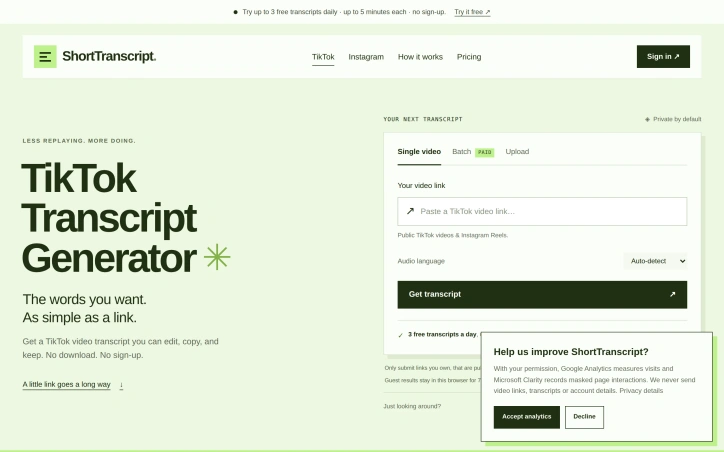
Extracting useful information from short-form video requires manual transcription. ShortTranscript addresses this friction with a browser tool that converts audio from public TikTok videos and Instagram Reels into timestamped text. The target audience is well-defined. Content creators use it to review their own performance or generate captions. Researchers preserve exact quotes from interviews and tutorials. Anyone building a reference collection from social videos can extract audio without manual typing. The workflow is intentionally minimal: paste a link, wait for processing, and edit the result. What distinguishes this product is its balance of accessibility and honesty. The free tier delivers genuine value: three daily transcripts up to five minutes each, with full editing and TXT export, no signup required. This removes barriers for casual use. Paid users choose one-time credit purchases rather than subscriptions, available at $4.99 for 150 credits or $19.99 for 800 credits, with each credit covering one started minute. Paid tiers unlock videos up to 60 minutes, batch processing of multiple links, and exports to subtitle formats including SRT and VTT. The tool operates from spoken audio rather than extracting existing captions, so it works on videos without subtitles. Transcripts arrive as editable segments with precise timestamps, allowing users to correct speaker names, adjust phrasing, and refine timing before exporting. Julian Tao operates it independently without affiliation to TikTok or Instagram, maintaining clear separation between this tool and the platforms it serves. The scope is deliberately narrow and transparently communicated. The tool handles English-language speech in accessible public videos only. It acknowledges common failure modes: music overlaying speech, overlapping speakers, and specialist terminology. Failed transcription attempts do not consume free allowances or charge credits, removing the penalty for difficult audio. ShortTranscript occupies a practical middle ground between casual and enterprise tools. It solves a specific problem without overextension. For creators, researchers, and note-takers gathering usable content from short-form video, it delivers core functionality at no recurring cost and without unnecessary complexity.
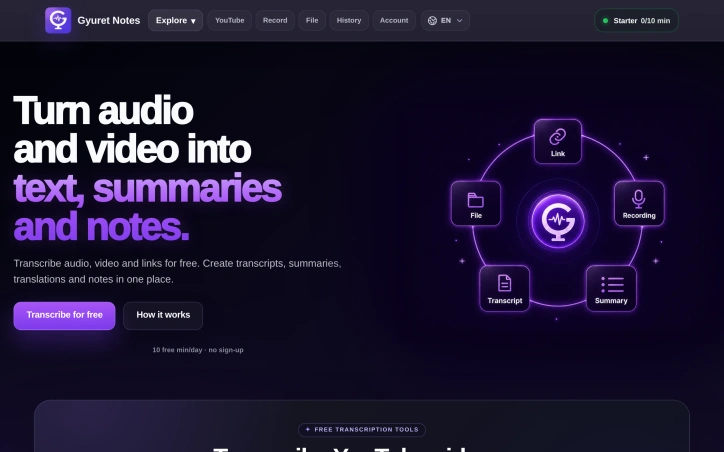
Audio and video transcription is increasingly essential for professionals, students, and content creators who need to convert spoken material into searchable, quotable text. Gyuret Notes addresses this workflow with an AI-powered transcription service that accepts multiple input formats and generates actionable outputs beyond basic transcripts. The platform accepts audio files in common formats (MP3, MP4, M4A, WAV), direct YouTube links, voice recordings, and audio captured from Chrome browser tabs—a capability particularly useful for remote workers transcribing meetings run through Google Meet or Zoom. Once transcribed, users can generate summaries that distill content to key points, create more granular notes for detailed documentation, or translate the output into other languages. This multilayered approach to post-transcription work distinguishes it from basic transcription-only tools that stop after converting speech to text. Gyuret Notes targets meetings, classes, interviews, podcasts, and voice notes, suggesting appeal across both professional and educational contexts. Remote workers managing team standups, students recording lectures, and content creators processing interview material would find the use case applicable. The product operates on a freemium model with three tiers. Users can start without creating an account and receive 10 minutes of free transcription daily. Signing in via Google extends free access to 30 minutes per day with permanent account history. The Pro tier costs $5 per month and increases the daily limit to 4 hours, providing 4,000 minutes of transcription monthly, along with ad removal. This tiered approach allows users to evaluate the service before committing to paid access. A practical design choice is account history, which preserves previous transcriptions. Users can revisit or reprocess earlier recordings without uploading files again. The platform runs on both web and Android, providing access across devices. The workflow is straightforward: add input through the chosen method, receive a transcript, generate summaries or detailed notes, translate if needed, then save or export the result. For users seeking a streamlined transcription tool valued for flexible inputs and post-processing capabilities, Gyuret Notes delivers. The generous free tier accommodates experimental use, while the summary and notes features address workflows that require distilling recorded content into actionable information rather than processing transcripts elsewhere.
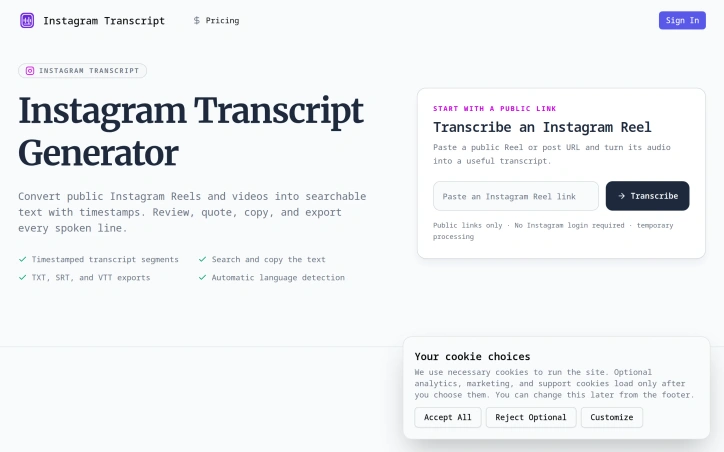
Converting video content into accessible text remains a persistent gap in content workflows, particularly for social platforms where audio-driven content dominates. IGTranscript addresses this by enabling users to extract searchable, timestamped transcripts from public Instagram Reels and video posts, transforming spoken content into reusable text without requiring login credentials or relying on existing captions. The tool fills a genuine need for creators, researchers, and content professionals who frequently need to reference, quote, or verify specific moments in video. Rather than scrubbing through footage to locate a particular statement, users paste a public Instagram link and receive a transcript indexed by time codes. This approach works regardless of whether the original content includes captions, since the transcription originates from the video's audio track. Several capabilities distinguish the product. The export options—supporting TXT, SRT, and VTT formats—make transcripts immediately compatible with subtitle workflows and editing software, extending their utility beyond simple note-taking. Timestamped segments anchor each line of dialogue to its position in the video, allowing users to verify quotes against the source before republishing. A search function within the transcript itself accelerates the process of locating specific names, phrases, or claims. Automatic language detection removes friction for content in languages beyond English, though users can override this to ensure accuracy. The implementation respects privacy by processing media temporarily rather than creating permanent public archives, and the platform explicitly restricts itself to public links, rejecting private accounts before processing begins. This design choice sidesteps account compromise and misuse vectors while keeping operations straightforward. The tool acknowledges its own limitations: transcript accuracy varies with source audio quality, background music, speaker accents, and overlapping dialogue. This transparency prevents overconfidence in edge cases where transcription might struggle. IGTranscript succeeds as a focused utility rather than an ambitious platform. It solves one problem thoroughly—making video audio searchable and citable—for users who regularly work with Instagram's video format. The lack of login requirements and the emphasis on data portability through standard subtitle formats position it as genuinely user-centered, not designed to create lock-in.
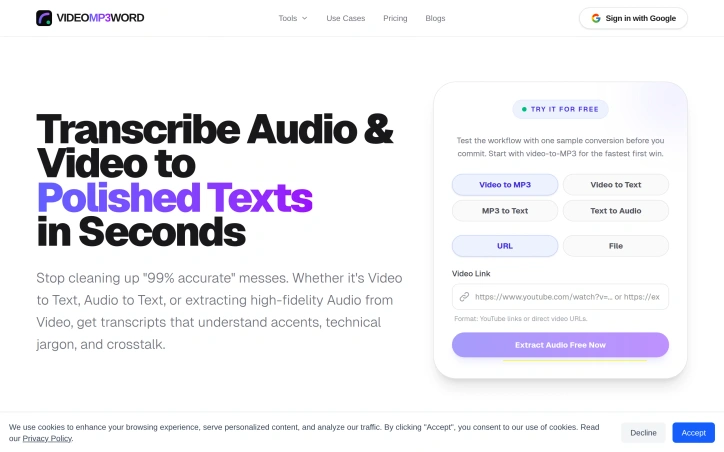
Transcription has long been the bane of knowledge workers—long recordings full of umms, ums, false starts, and throat-clearing that demands hours of manual cleanup. VideoMP3Word tackles this by combining multi-format transcription with an AI that understands context and industry-specific terminology, delivering polished, usable transcripts without the editorial drudgery. The product's core insight is that transcription quality isn't just about accuracy in speech recognition; it's about producing text that actually reads like finished writing. Rather than leaving filler words and repetitive phrasing intact, the system applies domain-aware filtering that strips verbal tics while preserving technical jargon. A laparoscopic cholecystectomy stays intact in medical transcripts, while casual "you knows" disappear—a distinction that generic speech-to-text tools routinely botch. This makes the output immediately usable for legal documents, medical records, educational content, and technical research where terminology precision matters. Speed stands out as a second major differentiator: the platform processes 60-minute recordings within three minutes, timestamped and ready for review. For content creators working under deadline pressure, this converts transcription from a bottleneck into a near-real-time capability. On the features side, VideoMP3Word handles multiple input formats (MP4, MOV, AVI, MP3, WAV, M4A, YouTube, Zoom links) and outputs to an extensive list—Word documents, PDFs, plain text with speaker labels, SRT/VTT/ASS subtitle files, and FLAC/MP3/WAV audio extraction. The system includes AI-generated summaries and millisecond-accurate timestamps, making it valuable for creators repurposing content into blogs and podcasts, as well as legal teams building searchable archives. Privacy is built into the architecture rather than bolted on as a feature. The company commits to zero-knowledge design, encrypted storage, non-retention of user files, and explicit task expiry controls—a direct answer to justified skepticism many professionals harbor about uploading sensitive recordings to cloud services. For regulated industries or confidential work, these guarantees provide clear value. The product invites users to test a single conversion free, a straightforward way to evaluate whether the accuracy and formatting align with specific needs. For organizations exhausted by post-transcription cleanup cycles, or professionals in regulated fields where both accuracy and privacy are non-negotiable, it's worth the trial.
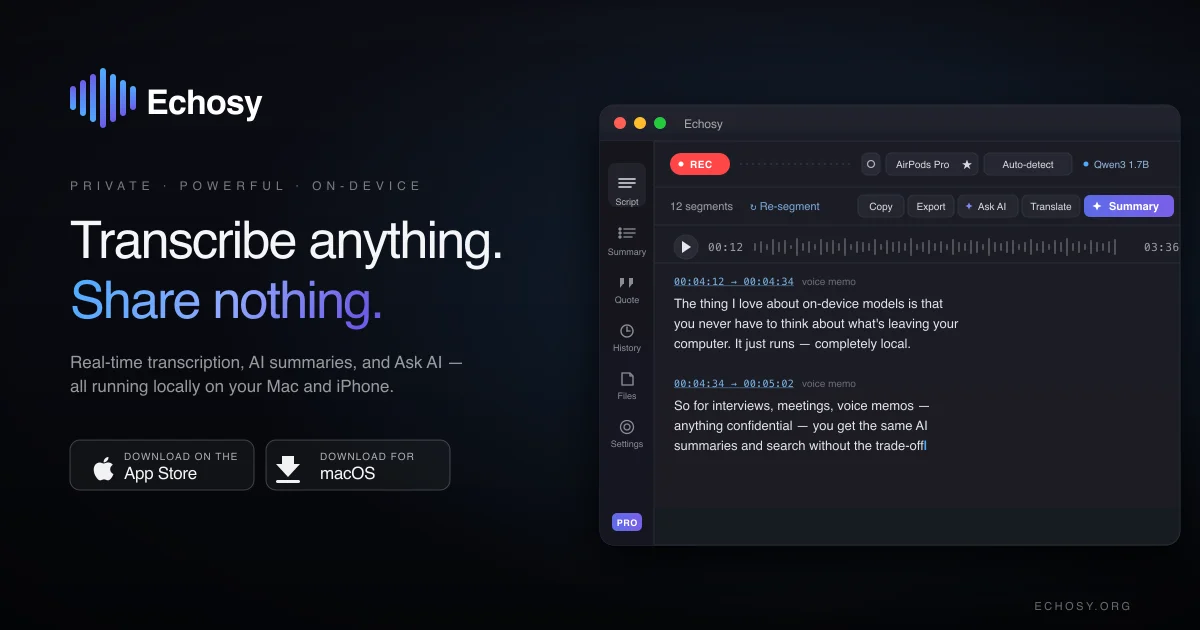
Privacy-focused audio transcription has become increasingly important as cloud-based services dominate the market, and Echosy addresses this gap directly by delivering professional-grade transcription entirely on macOS devices. The product targets professionals, educators, and content creators who need reliable transcription without surrendering their audio to external servers. The standout differentiator is its commitment to local processing. All transcription, summarization, and dictation happens on the user's Mac, eliminating latency and privacy concerns associated with cloud uploads. Rather than locking users into a single transcription model, Echosy supports multiple ASR engines including Qwen3-ASR and MLX Whisper, with GPU acceleration to optimize performance on Apple Silicon and Intel chips. This flexibility in model selection distinguishes it from more rigid competitors. Core capabilities span three major use cases. Live transcription captures both system audio and microphone input simultaneously with real-time timestamps, suitable for recording calls, lectures, and presentations. System-wide dictation activates anywhere on macOS via hotkey, with an Editor Mode that automatically inserts line breaks during pauses and supports voice-controlled formatting. File transcription accepts common audio and video formats for batch processing existing content libraries. What sets Echosy apart further is its integration with multiple LLM providers for summarization. Rather than forcing dependency on a single service, the platform supports OpenAI, Gemini, Ollama, and compatible APIs, allowing users flexibility in how they handle summarization workflows. Beyond summaries, users can chat directly with transcripts, extracting insights and action items. The service maintains searchable session history with audio replay, creating an archive of past recordings that remains fully accessible. The product is positioned as free-to-use software for macOS 14 and above, supporting both Apple Silicon and Intel architectures, with iOS availability as well. The emphasis on "no cloud, no latency, no compromises" clearly resonates with privacy-conscious users fatigued by default transcription workflows that involve external servers. For users skeptical of cloud-dependent transcription tools, Echosy offers genuine autonomy. It removes the friction of uploading files and waiting for remote processing, instead delivering instant results locally. The combination of multiple ASR models, flexible LLM integration, and comprehensive session management positions it as a credible alternative to cloud-centric competitors.
Video creators worldwide face a persistent challenge: making content accessible across language barriers while managing tight production timelines. LingoFrame addresses this friction by automating subtitle generation and translation, eliminating the manual work that typically consumes hours and requires specialized skills. The platform targets three distinct audiences effectively. Educators can caption lessons to reach international students without language constraints. Marketing teams gain the ability to deploy multilingual campaigns at scale. Content creators benefit from improved discoverability and accessibility, which have become competitive advantages in crowded platforms. What sets LingoFrame apart is its streamlined workflow. Users upload video files and the system generates subtitles automatically, then offers customization options before exporting. The product provides flexibility in output formats—creators can download standard SRT files for external use or burn subtitles directly into video files. Multi-language translation capabilities are built into the core offering rather than treated as a premium add-on, though the credit system does meter access to these features. The feature set covers the essential needs of the subtitling workflow. Beyond basic caption generation, the platform handles the technically demanding task of translating subtitles while syncing them to video timing. Customization options suggest users can adjust styling, formatting, and language specifics to match their content aesthetic and regional preferences. Pricing employs a credit-based model with tiered options. New users receive 25 free credits to trial the service, lowering friction for initial adoption. Paid plans start at $4.99 for 30 credits, with a mid-tier offering at $12.99 for 100 credits marked as the platform's most popular option, and a premium tier at $29.99 for 300 credits. The credit allocation system accounts for different operation costs—subtitle generation, merging, and translation each consume credits at different rates, though exact time-to-credit conversions require calculation. LingoFrame occupies a practical position in the accessibility tooling space. It doesn't attempt to be a full video editing suite or compete with enterprise-grade localization platforms. Instead, it solves a specific, high-friction problem with a direct interface and transparent pricing. The free credit allowance and popular mid-tier option suggest the company targets creators and small teams rather than enterprise deployments, prioritizing ease of use over feature maximalism. For any producer managing multilingual content, the value proposition centers on the time savings and quality standardization that automation delivers.
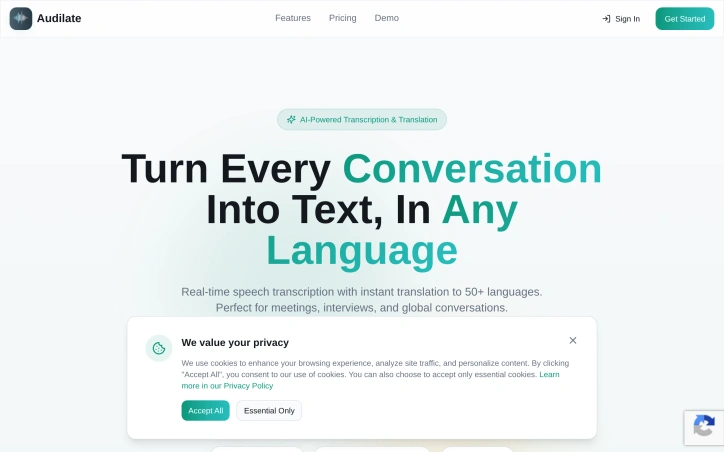
Breaking down language barriers during real-time conversations has long been a friction point for globally distributed teams, and Audilate directly addresses this challenge. The platform combines AI-powered speech transcription with simultaneous translation across over 100 languages, making it a practical solution for organizations where meetings, interviews, and collaborative discussions frequently span multiple geographies and language groups. The core value proposition centers on eliminating the lag and complexity that typically come with asynchronous translation workflows. Rather than recording conversations and processing them after the fact, Audilate delivers live transcription and translation, allowing participants to collaborate without stopping to manage language gaps. This is particularly relevant for companies hiring internationally, conducting cross-border partnerships, or operating distributed teams where English is not universally spoken as a first language. What distinguishes the product is its breadth of language support. With coverage across 100+ languages, the platform moves beyond serving just major language pairs and opens functionality to teams working in less commonly supported languages. This scope suggests the founders recognize that global collaboration extends well beyond English-to-Spanish or English-to-Mandarin scenarios. The integration of transcription and translation in a single workflow is also noteworthy—separate tools for these functions create unnecessary switching costs and synchronization challenges. The positioning emphasizes real-time processing, which is critical for the use cases mentioned. Whether facilitating a live meeting between team members in different countries, conducting remote interviews with international candidates, or enabling seamless cross-border conversations, the speed at which transcription and translation occur directly impacts usability. Delays of even a few seconds can derail natural conversation flow. The product targets organizations serious about global teamwork, particularly those for whom language support has become a competitive advantage or operational necessity. This includes multinational corporations, international service providers, distributed startups, and any team conducting work across language boundaries on a regular basis. The emphasis on meetings and interviews suggests the founders see their strongest initial adoption among HR, engineering, and business development functions that routinely conduct cross-language conversations. One practical consideration for potential users is how the platform integrates with existing communication infrastructure—meetings apps, video conferencing tools, and collaboration platforms—though those implementation details fall outside the scope of what's presented here. The foundational premise, however, is sound: removing language as a barrier to real-time collaboration remains a genuine problem for many organizations.