GPTZZZ
GPTZZZ 是面向开发者的独立第三方 AI API 中转与多模型网关,提供 OpenAI 兼容接口和 Claude Messages 接口,帮助应用与编程工具...
@fuck.it
Email privacy has become an afterthought at mainstream providers, which treat inboxes as data sources to be mined for ad...
Categories
Best AI Generative Media Startups & Tools
Generate images/videos from prompts, edit photos, and power creative workflows.
Recently Listed
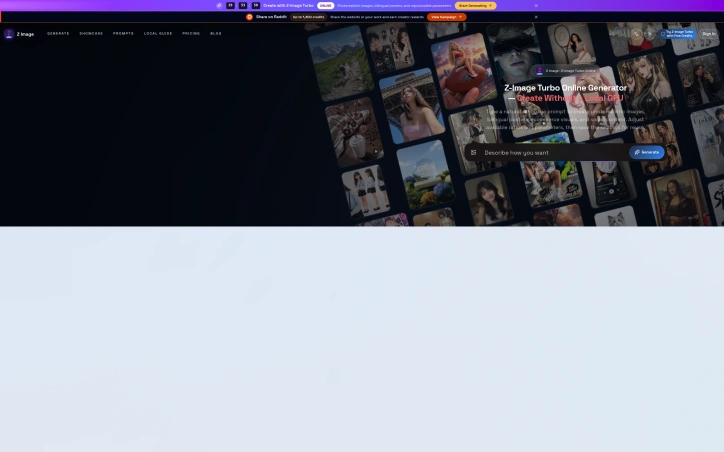
92 launchesOnline image generation typically requires either expensive local hardware or confusing, feature-bloated platforms. Z Image Turbo addresses this by offering a streamlined browser-based generator focused on the specific visual assets creators actually need: product photography, promotional posters, editorial portraits, social media content, and illustrations. The target audience includes small business owners managing ecommerce catalogs, marketing teams producing campaign materials, and independent creators who need polished visuals without technical friction or the time investment of learning complex software. The product distinguishes itself through deliberate simplification. Rather than overwhelming users with dozens of parameters, it presents practical templates organized by actual use case. A user looking to generate a product hero image gets a pre-written prompt structure optimized for that purpose. The same principle applies to categories like "Chinese Promotional Poster" or "Vertical Social Campaign," each with suggested aspect ratios and compositional guidance baked in. This workflow-first approach sidesteps the common problem of users staring at a blank text box unsure where to begin. Several design choices stand out. The platform supports bilingual content creation, particularly useful for teams producing materials in English and Chinese. The ability to save prompts, seeds, and settings for reuse addresses a real workflow need: creators often want to regenerate variations on a successful visual or maintain consistency across batches. Flexible aspect ratios accommodate different output requirements without forcing users into a square-only cage. The reference gallery demonstrates practical output across multiple categories, showing product photography that looks commercially viable rather than obviously AI-generated, editorial portraits with believable lighting, and illustrations with environmental detail. The generator operates entirely in-browser, eliminating the setup barrier that deters many potential users from local tools. This also means no GPU investment required on the creator's end. The platform offers free trial credits to test the service before commitment, lowering the barrier to initial experimentation. The positioning as a fast, focused alternative to both desktop GPU tools and sprawling web-based platforms should resonate with pragmatic creators who want generation speed without the learning curve. Whether the image quality and consistency of results justify regular use will determine whether this captures meaningful market share, but the product design itself reflects genuine thinking about how creators actually work.
Automating the tedious work of video production, this AI-powered tool tackles a genuine pain point for anyone trying to communicate complex ideas visually without video editing expertise or budget constraints. Creators, marketers, educators, and product teams can now convert raw material—a topic description, script, URL, or PDF—into a complete animated explainer video, handling everything from script generation and storyboarding through voiceover production and synchronized captions. The product's core strength lies in its scaffolded workflow. Rather than dumping an AI-generated video on users, it places a review step between input and output, letting creators approve and refine the storyboard before rendering. This human-in-the-loop approach addresses a real problem with fully automated video generation: the output often misses nuance or requires rework. By letting users course-correct early, the tool respects both their creative vision and their time. The visual flexibility stands out as well. The platform offers five distinct aesthetic directions—motion, illustration, infographic, character, and product visuals—letting users match the style to their content. The showcase examples demonstrate genuine variation in tone and execution, from upbeat lifestyle sequences to polished product demos and character-driven narratives. This breadth matters because an explainer video for financial software demands a different visual language than one for fashion or entertainment. Technical depth complements the accessibility. Beyond the web interface, the platform includes API access for developers and teams running high-volume generation workflows. This dual approach positions it as both a tool for individuals experimenting with explainer video creation and an infrastructure component for larger operations. The export flexibility—supporting 16:9, 9:16, and 1:1 aspect ratios—acknowledges that explainer videos now need to work across desktop, mobile, and social platforms. Multilingual voiceover generation and synchronized captions extend the appeal beyond English-speaking markets, a thoughtful inclusion that many simpler tools overlook. The ability to add background music rounds out the production value without requiring external audio editing. The presentation focuses heavily on creative capabilities and visual examples but notably omits pricing information, making it difficult to assess whether the tool competes on cost efficiency or positions itself as a premium solution. For anyone regularly producing educational or promotional content, the time savings alone justify investigation, particularly given how much of the heavy lifting—script writing, visual composition, voiceover production—typically falls on human creators. The tool doesn't eliminate creative decision-making; it eliminates the mechanical work that usually precedes it.
Accessibility sits at the core of what ReelMuse does: democratizing professional-grade video and image production through an all-in-one AI platform. The service targets creators of all skill levels, from casual content makers to aspiring producers, eliminating the technical expertise traditionally required to produce polished multimedia content. The platform consolidates several AI-powered creative tools under one roof. Users can generate original videos from scratch, produce high-quality images, and integrate AI-generated audio without specialized technical knowledge. The tool palette includes face-swap functionality and lip-sync capabilities, allowing creators to explore effects typically reserved for advanced editing software. These features signal a focus on trendy, shareable content formats that perform well on social media platforms. What distinguishes ReelMuse in a crowded AI creative tools space is its positioning as a comprehensive ecosystem rather than a point solution. The company has invested heavily in building a partner network, with verified listings across 22 different startup directories and AI tool aggregators. This breadth of third-party verification suggests institutional confidence in the platform. The company reports reaching over 50,000 active creators, indicating meaningful adoption. The partners page reveals deliberate strategy around link equity and domain authority, specifically mentioning dofollow backlinks and quick review cycles for partner exchanges. This demonstrates the company understands SEO fundamentals and is building visibility through quality partnerships rather than paid advertising alone. The curated nature of their partner list, emphasizing platforms serving AI enthusiasts and productivity-focused users, indicates targeted positioning toward creator communities. ReelMuse occupies interesting ground between consumer-friendly video editing tools and professional creative suites. The feature set prioritizes fast, template-based content creation focused on speed and shareability over cinematic sophistication. No pricing information is publicly disclosed. The aggregation strategy across directories and the emphasis on creator reach demonstrate that ReelMuse is betting on network effects and organic discovery. The company has built a foundation of accessible tooling and a thoughtful partner ecosystem, positioning themselves for growth in the rapidly expanding AI video generation category.
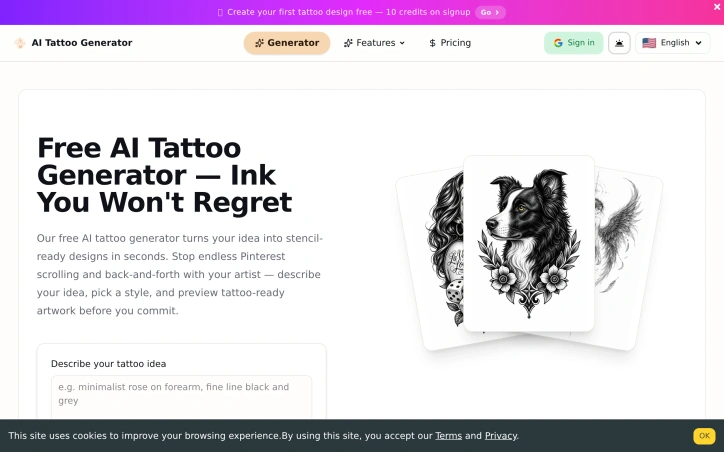
Translating a vague tattoo concept into a stencil-ready design has always meant weeks of Pinterest scrolling and awkward conversations with tattoo artists. AI Tattoo Generator cuts through this friction by converting text descriptions into preview-ready artwork in seconds, letting customers validate their vision before walking into an artist's chair. The product targets two distinct audiences: people who want to visualize and refine ideas independently before paying for professional consultation, and those seeking inspiration by browsing community-generated designs. Rather than positioning itself as a generic image generator, the founder built the workflow specifically for tattoo planning, training the AI on style-aware prompts for minimalist, traditional, Japanese irezumi, geometric, and blackwork aesthetics. What distinguishes this from standard AI image tools is the specificity embedded in every decision point. Users describe their tattoo idea, select from multiple AI models with different credit costs (ChatGPT Image at 4 credits, Doubao at 5, with premium options locked behind a Pro tier), pick an established tattoo style, and designate placement on specific body areas. The system delivers high-resolution PNG files formatted explicitly for artists to trace and adapt. This deliberate architecture—combining style, placement, and output format in a single workflow—reflects genuine product thinking about how tattoos actually get made. The community gallery functions simultaneously as inspiration and social proof. Displaying previous user prompts alongside finished designs creates a browsable archive of ideas, while a private mode upgrade lets users keep designs confidential. The font generator addresses lettering requests, a common tattoo need that most AI tools handle poorly. Accessibility comes through a free credit allowance on signup, allowing new users to generate multiple concepts before deciding whether to continue. Credit costs vary by model availability and capability, introducing a tiered monetization model without forcing immediate payment. The positioning is refreshingly honest: these are drafts, not finished pieces. The site consistently reminds users that AI designs are starting points requiring professional artist review and adaptation for actual skin placement. This liability-conscious language protects both the user and the company. For people frustrated by the design-communication gap in tattoo planning, the product delivers genuine utility. It collapses what might take days of conversation and revision into minutes of generation and variation.
Designers and marketing teams struggling to generate complex, information-dense visuals have a new option in Seedream 5.0 Pro, an AI image generator that combines detailed text prompts with reference imagery and interactive annotation tools to produce professional-quality outputs. The core value proposition centers on speed and control. Rather than iterating through countless text-based attempts, users can upload a reference image, mark specific elements with annotations—points, regions, sketches, or arrows—and use those marked areas within their prompt to guide the AI's refinement process. This hybrid approach bridges the gap between fully automated generation and fully manual design work, giving designers meaningful control over the AI's output while retaining the efficiency gains of generative tools. The product targets three distinct use cases. First, complex infographics and data visualizations where precision matters, from highly detailed interfaces to statistical dashboards. Second, product and marketing campaigns requiring photographic quality and stylistic coherence across multiple assets. Third, multilingual creative content, a feature enabling teams working across languages to maintain design consistency without manual rework. The examples demonstrate genuine capability: a dense RPG interface prompt generates what appears to be a functional, grid-aligned layout with readable typography and appropriate color restraint. Key capabilities include support for high-density infographics through mark-guided editing, photographic-quality rendering, and native multilingual generation. The interface appears straightforward, with users inputting visual and textual references within specified limits, accompanied by clear content guidelines around restricted material. What distinguishes Seedream from broader AI image generators is its explicit focus on complexity rather than simplicity. Competitors often optimize for photorealistic portraits or stylized illustrations; Seedream specifically targets dense data visualization, technical specifications, and intricate layouts. The reference image plus annotation system represents a meaningful UX innovation that acknowledges designers don't want fully autonomous generation—they want smart tools that respond to structured creative direction. No pricing information appears in the available material, making cost assessment impossible. The product positions itself for professional creative workflows, though the actual pricing tier would significantly influence whether it becomes a standard design tool or remains a specialized premium option. For teams handling high-complexity visual projects, the focused feature set suggests a clear understanding of niche market needs, regardless of eventual cost.
Creative professionals looking for inspiration when facing project blocks have found a dedicated tool in this hybrid creature generator. Built for artists and game designers, the platform combines random selection across 2,500+ animal species into single creatures with eleven distinct body parts, creating endless drawing prompts and character concepts on demand. The product's strength lies in its structured approach to randomization. Rather than selecting a single species at random, users click through eleven separate slots—base body, head, ears, eyes, nose, legs, feet, tail, coat, color, and an extra feature—each pulling from the deep animal database independently. This part-by-part assembly creates far more varied and unusual combinations than simple species selection would allow. Users immediately receive a text prompt describing their hybrid creature, which they can copy for sketching, sharing, or direct use in creative work. The platform targets several specific use cases effectively. Aspiring artists use the generated prompts as drawing practice exercises. Game designers and tabletop role-playing groups draw character concepts from the descriptions. Social media users share their generated creatures as community challenges or portfolio pieces. A gallery of featured community creations demonstrates how the AI-generated images from successful hybrids look in practice, showing pairs of creatures alongside the animal-part prompts that produced them. Monetization enters once users unlock the full feature set. Free usage includes revealing all eleven parts and generating the text prompt. Signing in unlocks AI image generation using GPT Image 2, though the platform also offers a hand-drawn concept sketch option credited at one unit. The combination of free core functionality with optional premium image generation creates accessibility without eliminating a path to revenue. The database draws from diverse animal categories including mammals, birds, reptiles, insects, recognized breeds, and lesser-known species, providing the breadth necessary for the tool to remain fresh across repeated use. The straightforward mechanics—click to spin each slot, reveal parts sequentially, copy or generate—require no tutorial or learning curve. For creative professionals seeking structured randomization rather than pure chance, or for anyone needing quick character design inspiration, this generator delivers focused utility within a narrow, well-executed scope.
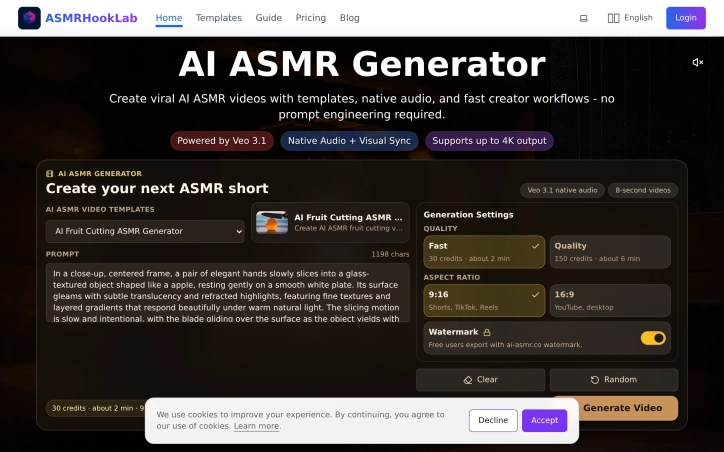
Creators chasing viral moments on social media face a persistent friction point: ASMR content production demands both technical skill and time investment. ASMRHookLab addresses this by enabling rapid generation of ASMR videos through AI, built on Veo 3.1 technology. The product targets short-form creators on TikTok, Reels, and YouTube Shorts who want to capitalize on ASMR's popularity but lack specialized equipment or editing knowledge. The central innovation is simplicity. Rather than requiring users to master prompt engineering, the platform provides templated workflows. Creators select a preset template like fruit cutting or keyboard tapping, adjust a handful of variables, and receive a complete video with synchronized native audio within minutes. This is a fundamental departure from most AI video tools, which place the burden of articulate prompting on the user. By removing that barrier, ASMRHookLab democratizes a content category that previously demanded both artistic vision and technical fluency. The feature set reflects this philosophy. Templates come prebaked with detailed visual direction and sound design guidance, eliminating guesswork about what makes ASMR satisfying. Native audio synthesis ensures that visual motion and sound truly align, a critical requirement for ASMR where the auditory experience drives engagement. The platform supports multiple output formats including 4K and handles both portrait (9:16) and landscape (16:9) aspect ratios, letting creators repurpose content across different social platforms in a single workflow. Generation speed varies by quality tier. Fast rendering consumes 30 credits and takes approximately two minutes, while higher-quality output requires 150 credits and six minutes. The credit system implies a freemium model where users can sample the product, with free accounts applying a watermark to exports. This pricing structure allows creators to test viability before committing spending, a pragmatic approach to trial and adoption. What distinguishes ASMRHookLab is its focus on removing complexity rather than adding features. Many AI video tools optimize for maximum customization, appealing to advanced users. This product optimizes for speed and accessibility. For a creator trying to test whether ASMR content resonates with their audience, or for someone seeking fast turnaround on trending formats, the tradeoff is favorable. The templated approach inherently limits creative range, but it trades depth for velocity, a calculation that aligns with short-form content rhythms where posting frequency often outweighs individual production polish.
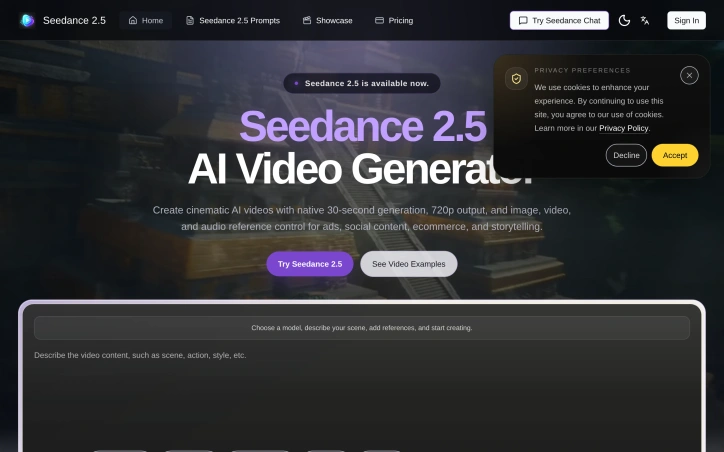
Cinematic video production without the traditional overhead is increasingly central to marketing and storytelling, and this AI-powered tool addresses a specific friction point: existing generators excel at short clips but struggle to maintain coherence across longer narratives. Seedance 2.5 targets creators, marketers, and production teams who need polished 30-second videos for ads, product launches, fashion content, and social media but lack the time or budget for conventional shoots. The product's core distinction is its approach to reference-based generation. Rather than relying solely on text prompts, it lets users provide images for style consistency, video references for motion guidance, audio tracks, and character references to maintain visual continuity throughout a 30-second sequence. This transforms the workflow from typing a description into something closer to traditional directorial planning—laying out beats, establishing visual anchors, and letting the model respect those choices across the full output. Beyond multimodal input, the technical architecture treats video as a joint audio-video generation task rather than post-processing sound into separately-generated footage. The 30-second native generation is mechanically significant; most competing tools max out at shorter segments and require stitching multiple clips together, a process the founder describes as tedious and prone to continuity breaks. Seedance 2.5 promises to render complete scenes with smoother narrative flow in one pass. The editing capabilities merit attention as well. Rather than forcing a full regeneration when details need refinement, the tool supports local region edits that preserve the composition, motion, lighting, and character identity of the broader scene. This substantially reduces iteration time for creators making small adjustments. The showcase examples span film, advertising, fashion, music, and educational content, demonstrating breadth in output quality and style versatility. Scenes range from surreal fantasy (floating storm battlefields, mechanical creatures) to grounded urban and commercial setups, suggesting the model generalizes reasonably well across visual genres. The platform does apply content screening, blocking requests involving sexual content, violence, hate speech, illegal activity, and rights-infringing material—a standard safety measure that may constrain some creative use cases. Pricing is not disclosed in the available materials, though the interface mentions a credit system. For teams evaluating the tool, transparency on cost-per-minute, subscription tiers, or per-generation pricing would be necessary for a practical procurement decision. The product positions itself as solving a real production problem with capabilities that distinguish it from simpler prompt-based generators, though buyers will need to validate consistency and edit speed against their specific workflow requirements.
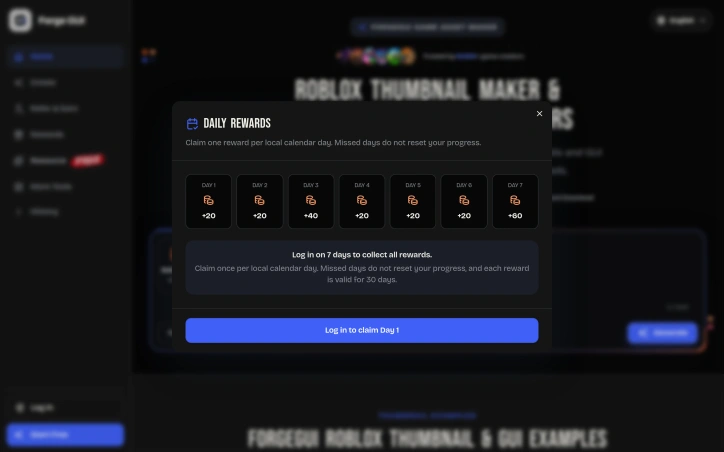
Game creators face a persistent friction point: compelling thumbnails and interface assets can drive engagement, but producing them individually consumes time and requires platform-specific visual knowledge. ForgeGUI addresses this directly by using AI to generate game thumbnails and GUI elements from text descriptions or reference images, with preset aesthetics matched to popular platforms. The product targets an active community of indie developers across Roblox, Minecraft, Unity, and Fortnite ecosystems. Rather than commissioning art or learning design tools, creators can describe a scene, apply platform-specific styling, and iterate rapidly on visual concepts. Several design choices distinguish ForgeGUI's approach. The platform presets go beyond generic filters—each targets a distinct visual language. Roblox-style output reflects blocky character proportions and environment aesthetics. Minecraft presets emphasize voxel-based forms. These constraints matter because thumbnails function differently at small viewport sizes on mobile devices, where contrast and subject readability determine click-through rates. ForgeGUI acknowledges this limitation directly, designing compositions for 16:9 mobile-friendly framing. The workflow itself prioritizes iteration. Users describe what they want, generate an image, then refine through edited directions or reference uploads rather than restarting from scratch. A live preview helps validate concepts before finalizing. The ability to test multiple visual moods—comparing scene staging, character expressions, or art directions within a single prompt—lets creators validate positioning before committing to one direction. A secondary feature set covers GUI assets beyond thumbnails: menus, panels, buttons, HUDs, and icons. The product labels 3D generation as coming soon, suggesting roadmap expansion beyond 2D web output. The company markets itself as trusted by over 10,000 creators and offers a 7-day free trial to assess the tool without commitment. No pricing structure appears in the public-facing content, leaving the long-term cost model unclear to prospective users. ForgeGUI works within constraints that define many AI generation tools: output quality depends on prompt clarity and how well style presets align with user intent. Creators expecting pixel-perfect professional work or highly customized branding will likely find the templated approach limiting. The core value proposition remains clear though—for creators who need functional game assets faster than manual creation allows, with minimal design expertise required, this directly shortens the iteration cycle.
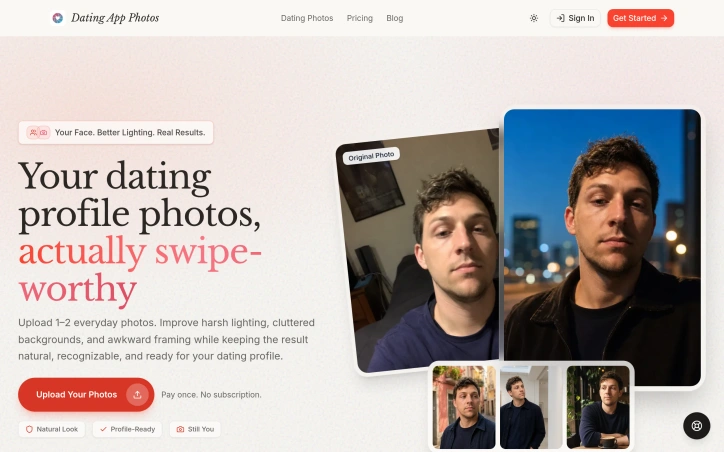
Poor lighting and awkward framing sabotage many dating profiles before a conversation even starts. Dating App Photos tackles this directly, using AI to rehabilitate everyday photos into polished profile images without requiring a professional photographer or extensive editing. The service lets users upload one or two casual photos and, after answering a few quick questions, receive a complete gallery of enhanced versions. The core transformation focuses on three technical improvements: correcting harsh lighting conditions, reframing awkward compositions, and removing visual clutter from backgrounds. What distinguishes this product is its emphasis on preserving the user's recognizable appearance while applying these adjustments. The results maintain a natural aesthetic rather than pushing toward an unrealistic or heavily filtered look. Dating App Photos offers six distinct scene templates that anchor transformations to believable everyday contexts: a coffee shop vibe, outdoor activity shots, smart casual styling, energetic poses suggesting an active lifestyle, cozy indoor settings, and candid street scenes. This approach sidesteps the artificiality that undermines many AI photo services, grounding results in scenarios that feel authentic to how users actually live. The product's positioning emphasizes speed and convenience. Traditional approaches require hiring a photographer and coordinating availability; this service compresses the workflow from hours or days to minutes. Users also retain full control, reviewing each generated image before committing it to their profile. On the business model front, Dating App Photos operates on a simple one-time payment structure with no recurring subscription fees. Users receive 30-day download access to completed images. The privacy stance is straightforward: photos are processed privately and never displayed publicly or used for other purposes. For people struggling with poor-quality existing photos but hesitant to hire professional photography services, this fills a genuine gap. Dating app users face real pressure to present themselves effectively, and lighting and framing issues create a barrier regardless of actual appearance. By automating these specific corrections while preserving identity, Dating App Photos addresses a real frustration in the user journey without requiring expensive alternatives.
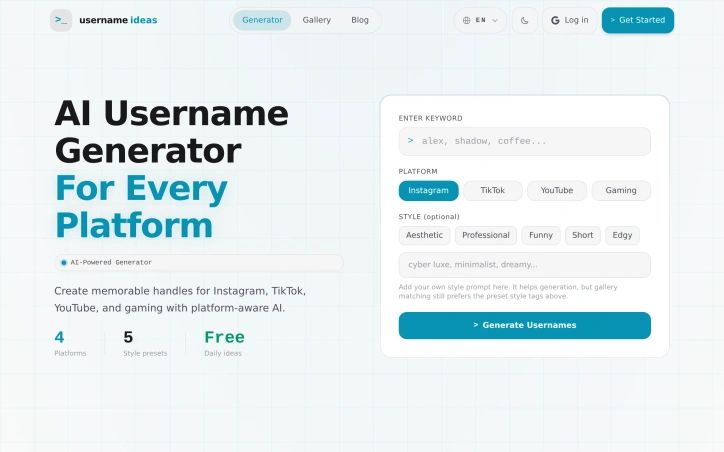
Finding a unique username that works across multiple social platforms represents a genuine friction point for creators, gamers, and casual users alike. Username Ideas Generator addresses this friction head-on with an AI-powered solution designed to streamline the brainstorming process. Rather than cycling through variations manually or settling for usernames already claimed elsewhere, users can leverage the tool to generate aesthetic and memorable options tailored to their needs. The tool targets the workflow across major platforms: Instagram, TikTok, YouTube, and gaming communities. This multi-platform focus recognizes the reality that many creators maintain presence across several channels and need consistency. The AI-driven approach to generation distinguishes it from simpler random generators or availability checkers; the tool produces suggestions aimed at being both memorable and visually appealing, rather than defaulting to number combinations or special character strings that clutter most username fields. What makes the product compelling is its directness. The founder built this after experiencing the tedium firsthand, and that clarity of purpose translates into a focused scope. Rather than attempting to solve username management broadly, it concentrates on the initial generation phase where most of the creative friction occurs. The tool saves users from repetitive manual searching and the cognitive load of balancing originality against availability constraints. The positioning as "aesthetic" and "memorable" also signals an understanding of platform culture. A good TikTok username differs substantially from a gaming handle, and an effective Instagram name requires different sensibilities than a YouTube channel. The tool's ability to generate ideas specific to each platform reflects this distinction. What remains unclear from the available information is how the AI determines what constitutes an aesthetic username in context-specific ways, or how it validates availability across platforms. The speed advantage is evident in the problem statement, but the actual user workflow and learning curve remain undescribed. Despite these questions, Username Ideas Generator solves a real problem with a straightforward approach that could save creators meaningful time during the account setup phase.
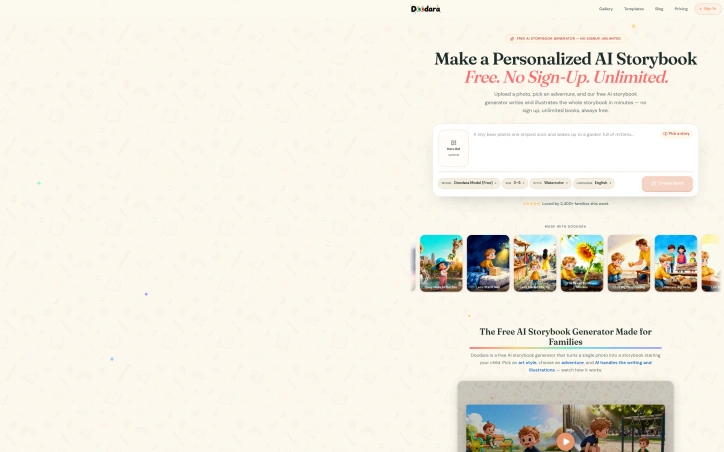
Personalized children's picture books typically require either significant expense or design expertise—two barriers that most families lack. Doodara removes both by generating illustrated storybooks in minutes from a single photograph, requiring neither sign-up nor payment. The product's strongest asset is its frictionless entry point. Users upload a photo, select from twenty story templates or write their own premise, choose from sixteen art styles ranging from watercolor to pixel art, and the AI generates a complete book with consistent character illustrations throughout. The entire process completes in minutes, with no account creation necessary. This approach democratizes book creation: parents and caregivers can produce polished, personalized stories their children actually feature in—something previously limited to custom book publishers with premium pricing. The execution details matter. The service handles character consistency across pages, a non-trivial problem in generative AI that often produces jarring inconsistencies. It offers multiple output formats: flipbook previews for immediate sharing, downloadable PDFs for printing, and various aspect ratios optimized for different devices. These aren't afterthoughts; they embody the founder's core belief that giving each child the experience of starring in their own narrative deserves accessible tools. The service has generated over 2,400 books and demonstrated strong user adoption. The business model uses freemium monetization: the free tier delivers complete functionality using a standard AI model, while paid plans unlock an advanced model option, commercial usage rights, and additional printing services. This approach positions the free tier as a legitimate product, not a limited trial designed to frustrate users into upgrading. What remains unclear from the marketing materials is how consistently the AI handles edge cases—children of different ethnicities, more complex story concepts, or unusual art style combinations. The consistency promise is strong, but edge case performance determines whether this remains genuinely inclusive for all families. Doodara solves a real problem in an elegant way. It eliminates the skill, cost, and complexity barriers that prevented most families from creating personalized books. The free tier is genuinely unlimited and functional, making this accessible to households of any income level. For parents seeking a memorable way to put their child at the center of a story, this tool delivers.
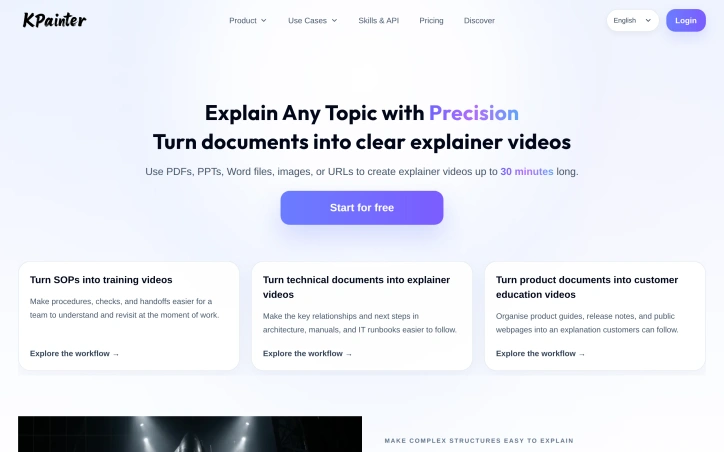
Organizations struggling to communicate complex procedures, technical specifications, and product information face a persistent problem: dense documents fail to engage learners. KPainter addresses this gap by automating the conversion of static source materials into structured video explanations. The platform accepts a broad array of input formats—PDFs, PowerPoint presentations, Word documents, spreadsheets, images, and URLs—then transforms them into videos up to thirty minutes long. Rather than replacing source materials, KPainter uses them as the foundation for visual storytelling, letting creators specify their target audience and desired outcome before the system generates an explainer. This source-led approach distinguishes it from generic animation tools that require starting from scratch. The use cases on display span corporate training, technical communication, and customer education. Teams can turn standard operating procedures into onboarding walkthroughs, convert architecture diagrams and IT runbooks into clear dependencies, and package product guides and release notes into customer-facing videos. The platform also handles data storytelling, animating financial results and engineering specifications into narrative form. Examples shown include explaining rocket design, visualizing blood flow through the heart, and demonstrating how lithography machines work step by step. What stands out is the platform's flexibility around input types and visual complexity. Rather than forcing users to script videos from narrative first principles, KPainter lets them begin with real assets—an existing manual, a company image, an architectural diagram—and translate those into video. The remix capability, allowing users to review and refine generated content, suggests the tool handles the heavy lifting of visual organization while preserving creator control. The pricing model starts with a free tier, though specific plan details and premium features are not disclosed in available materials. This freemium approach lowers the barrier for teams experimenting with video-driven documentation. The platform targets organizations facing a common efficiency problem: knowledge locked in text-heavy formats that don't stick. By automating the creation of structured video explanations from existing materials, KPainter compresses what would otherwise require significant video production effort, scriptwriting, and animation skills.
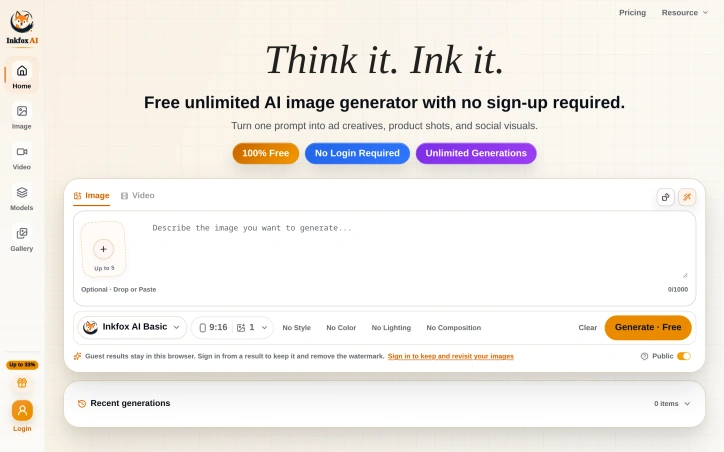
The demand for AI-generated images has surged across various industries, but existing solutions often come with limitations such as restricted generation capabilities and mandatory sign-ups. Inkfox AI addresses these pain points by offering a free, unlimited AI image generator that doesn't require users to create an account. At its core, the platform is designed to simplify the process of creating diverse visuals from a single prompt. Users can input their desired image description and generate multiple ad creatives, product shots, and social media visuals. The absence of a sign-up requirement makes it instantly accessible, allowing users to start generating images right away. One of the standout features of Inkfox AI is its ability to produce unlimited generations without charging users. The platform provides options to customize the output by selecting between image and video, and it allows for some level of control over the generation process through parameters such as style, color, lighting, and composition. However, users should be aware that results generated without signing in are confined to the current browser session and will include a watermark. Users who don't sign in will have their results stored locally in their browser, and these results will be watermarked. Signing in offers the benefit of retaining generated images and removing the watermark. The simplicity of the generation process, coupled with the flexibility to create a variety of visuals, makes Inkfox AI an attractive option for users seeking to leverage AI-generated imagery. Inkfox AI is notable for its straightforward, no-frills approach and commitment to being 100% free with unlimited generations. This business model is explicitly stated, with no additional pricing tiers or caveats mentioned on the website. Overall, Inkfox AI is well-suited for individuals and businesses looking for a hassle-free, cost-effective solution to generate AI-based visuals.
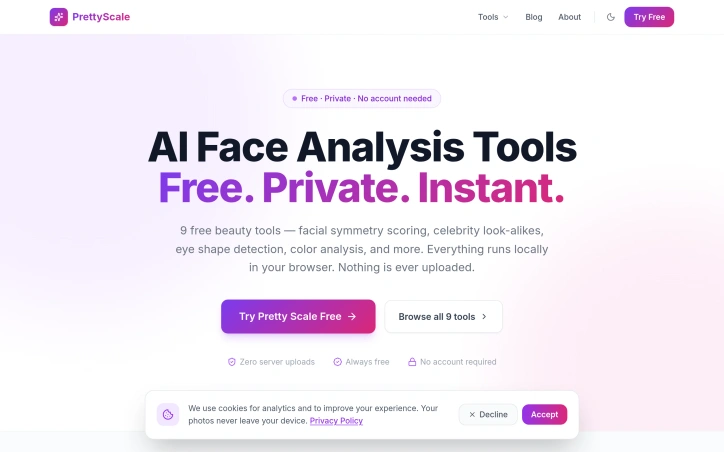
In the realm of beauty analysis, concerns about privacy often hinder users from exploring their features in-depth. To address this, a novel solution has emerged, prioritizing user privacy while providing a suite of AI-powered beauty tools. The driving force behind this innovation is the need for a secure and confidential platform where users can analyze their facial features without compromising their personal data. By ensuring that all analyses run locally within the user's browser, the solution effectively eliminates the risk of sensitive information being shared or stored. What stands out about this product is its commitment to maintaining user privacy while delivering a comprehensive range of beauty analysis tools. The absence of server uploads and data collection mechanisms underscores this commitment. Notably, the AI-driven tools are diverse, encompassing facial symmetry scoring, celebrity look-alikes, face shape detection, and color analysis, among others. Key features worth highlighting include the ability to analyze 468 facial landmarks for precise assessments and the availability of personalized style tips and recommendations based on the analysis. The product offers nine distinct tools, each designed to cater to different aspects of beauty analysis, from determining face shape and eye shape to estimating age and identifying the most flattering colors. The product is touted as being free forever, with no hidden costs or account requirements, making it accessible to a wide range of users. By forgoing a traditional revenue model that relies on user data or subscription fees, the developers have successfully created a unique value proposition centered around privacy and accessibility.
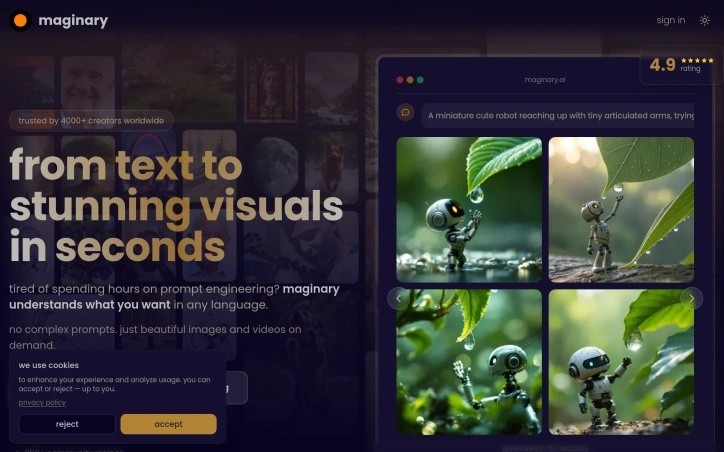
Creating stunning visuals from text prompts just got a lot easier, thanks to a innovative AI-powered solution designed specifically for creators. The problem it tackles is the tedious and time-consuming process of crafting complex prompts to achieve desired results, freeing up artists to focus on their craft. What stands out about this product is its ability to understand intent in any language, allowing users to simply write in plain language and receive high-quality images and videos on demand. The AI engine is capable of delivering diverse and unique outputs, making it an ideal tool for those who need rapid iterations and varied results. Notably, the product boasts a range of key features, including the ability to generate four variations in seconds, making it perfect for tight deadlines. It also offers style references, video generation, and more, built right in. Additionally, users can integrate the product into their workflow via a full REST API with comprehensive documentation and examples. The pricing model is straightforward, with a pay-as-you-go approach that eliminates forced subscriptions. Users can choose from a range of plans, including a novice pack with no commitment, or higher-tier plans with varying levels of support and credits. All plans include full commercial rights, with no hidden fees, and users can cancel anytime. With over 600 creators worldwide already trusting this product, it's clear that it's making a significant impact in the creative community. By simplifying the process of creating stunning visuals, this AI-powered solution is empowering artists to bring their ideas to life quickly and easily.
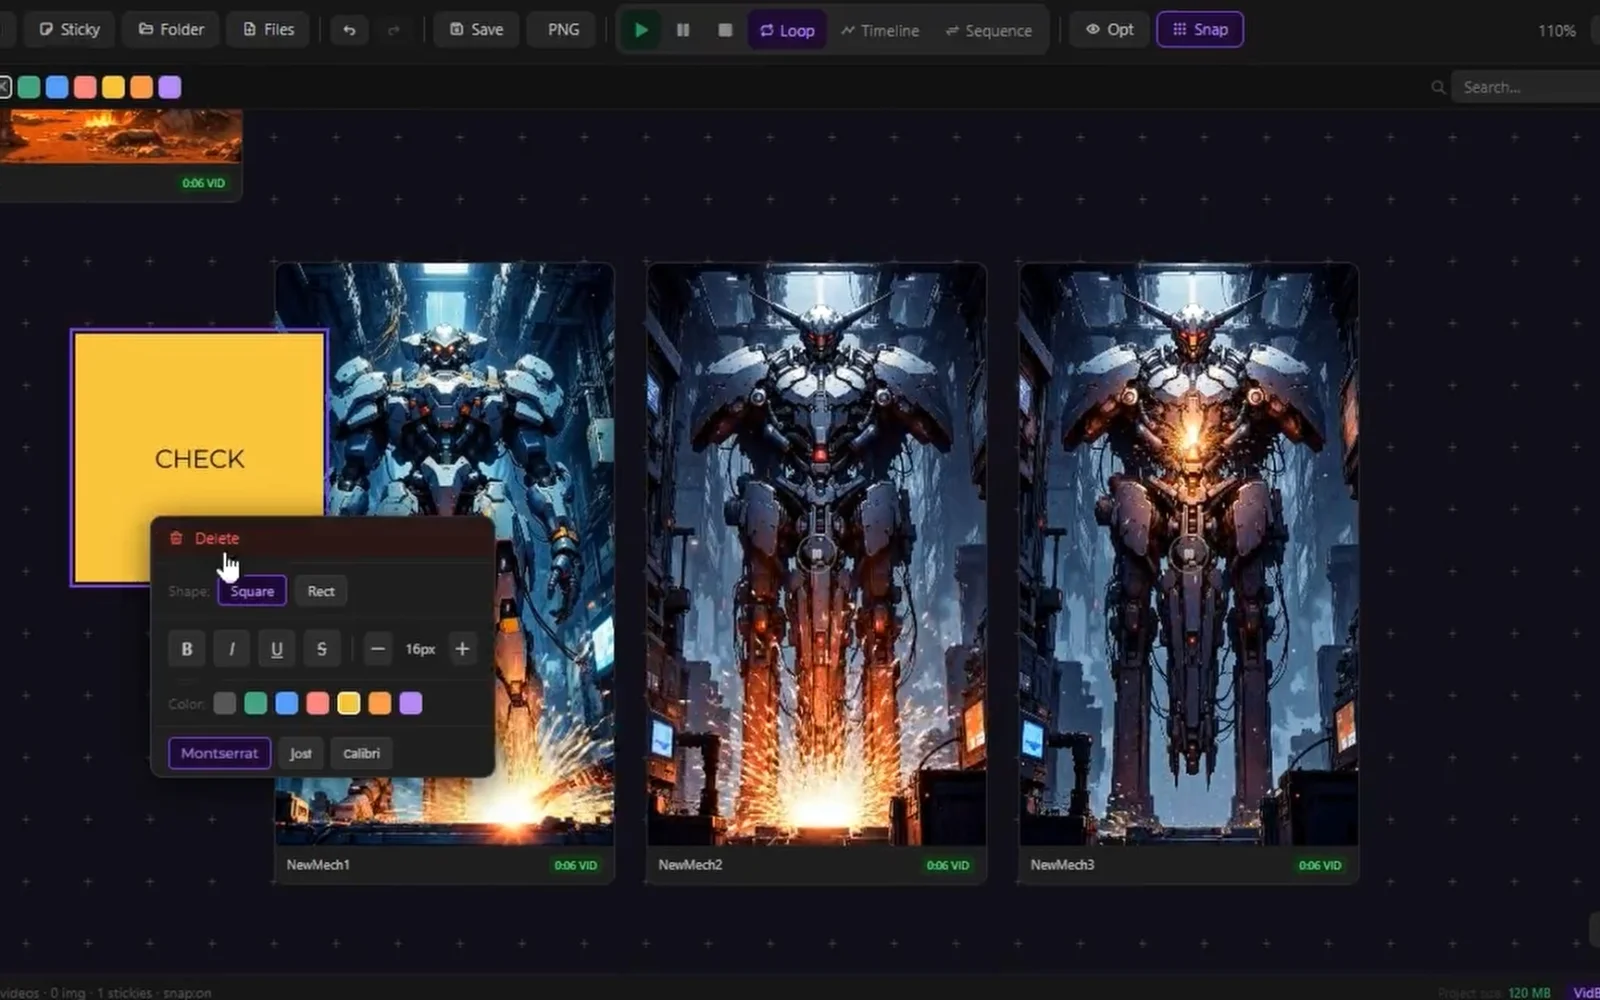
Creators working with AI-generated media face a fragmented workflow. After spending time generating images and videos across various AI tools, they must jump between multiple applications to organize, compare, and present their results. VidBoards consolidates this repetitive context-switching into a single, focused application designed specifically for reviewing and presenting generated batches. The product targets AI creators actively using generation tools like ComfyUI, Automatic1111, Stable Diffusion, and similar platforms. Rather than building yet another creation tool, VidBoards solves the problem that comes after generation: managing outputs efficiently, comparing results systematically, and presenting sequences without leaving the application. What distinguishes VidBoards is its philosophical foundation. The application operates entirely locally without subscriptions, accounts, or cloud services. It reads embedded metadata directly from generated files, eliminating manual documentation burden. This approach appeals to creators who prioritize privacy and control over their workflow. The interface centers on an infinite canvas where users arrange videos and images freely using standard gestures: middle-mouse panning, scroll-wheel zooming, and optional snap-to-grid alignment. Multiple boards support unlimited cards per project, saved as lightweight .vdb files. The architecture remains deliberately simple, keeping users focused on their media rather than fighting interface complexity. The shared timeline feature represents the core innovation. A single scrubber syncs all videos to the exact same frame simultaneously, enabling instant comparison across dozens of clips. Rather than opening multiple players and mentally tracking differences, creators see frame-by-frame variations across all takes at once. This directly addresses the time spent hunting for optimal shots. Sequence Mode transforms the application into a presentation tool. Users activate a full-screen overlay, arrange clips in order, and play them back-to-back like a showreel. Auto-advance between items and keyboard controls eliminate the need to export to external presentation software. Supporting tools include batch operations through multi-select, quick media controls for simultaneous playback or looping, and support for PNG, JPEG, WebP, MP4, and MKV formats. The application also handles metadata from multiple AI generation tools seamlessly. The pricing model is unambiguous: free, forever, with no subscription, no account requirement, and no cloud dependency. For a creator-focused tool addressing a specific workflow bottleneck, VidBoards demonstrates disciplined product design aligned with its audience's actual needs.
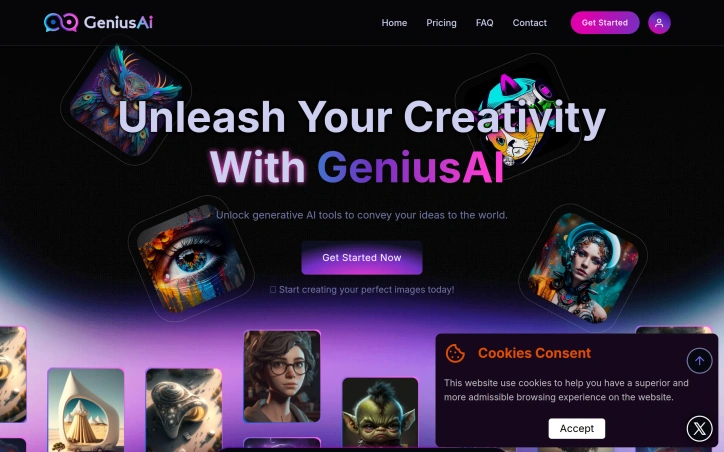
Creative professionals and businesses struggling to generate high-quality visual content at scale now have access to a streamlined AI image generation platform that prioritizes both speed and ease of use. GeniusAI targets content creators managing production timelines, marketing teams running campaigns, and developers building AI-powered applications, offering a tiered approach that accommodates different user needs and budgets. The platform distinguishes itself through deliberate simplicity. Rather than overwhelming users with endless customization options, GeniusAI presents a three-step workflow: select from preset AI models and styles, describe what you want in natural language, and generate the image. This straightforward approach appeals to users without technical AI expertise while providing enough control for professionals seeking consistency across projects. The product features image generation with multiple model variants, photo editing tools, and image upscaling capabilities. Prompt enhancement automatically improves user descriptions before generation, reducing the friction of crafting perfect prompts. Teams can collaborate within a shared workspace, and all tiers include commercial licensing, removing legal uncertainty around using AI-generated content for business purposes. For developers, an API enables integration with existing workflows and the ability to enforce brand guidelines programmatically. GeniusAI's pricing structure reflects its market positioning. The entry-level Genius Creator tier at ten dollars monthly offers 700 monthly credits sufficient for casual creators, with images up to 896 by 896 pixels and access to eight preset styles. The Genius Studio tier at thirty-five dollars monthly jumps to 3,000 credits and increases resolution to 1024 by 1024 pixels while unlocking all 21 available styles. The Genius Pro tier at forty-five dollars monthly adds 5,000 monthly credits, extends creation history to unlimited, and includes twenty-four hour priority support. Each tier supports instant regeneration and full-size downloads. The generation process emphasizes speed; the platform can produce images in seconds rather than minutes, a meaningful advantage for professionals with tight deadlines. The inclusion of multiple generation modes allows users to balance output speed against visual polish depending on project requirements. The platform's positioning emphasizes both accessibility and professional capability, suggesting it serves as a bridge between casual users discovering AI-generated imagery and teams deploying it as part of their production workflows. The combination of competitive pricing, commercial licensing, and team features positions GeniusAI as a practical choice for businesses integrating generative AI into existing creative operations.
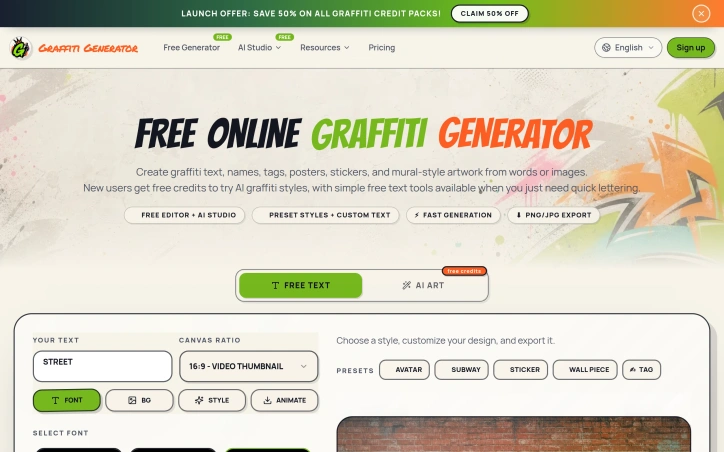
Graffiti Generator is built for creators, designers, students, content makers, small brands, street-art fans, and anyone who wants to turn words, names, tags, or prompts into graffiti-style visuals without learning complex design software. The platform combines free browser-based graffiti tools with AI-powered graffiti image generation. Users can create graffiti text designs, explore name and tag styles, browse graffiti letter pages, generate AI graffiti artwork from prompts, and download results for personal projects, social graphics, posters, stickers, moodboards, profile images, and creative concept work. Unlike a generic AI image generator, Graffiti Generator is focused specifically on graffiti and street-art workflows. It supports different creative entry points: a word, a name, a tag, a single letter, a full prompt, or a source image. This makes it useful whether someone needs a quick graffiti text preview or a more detailed AI-generated mural-style image. Graffiti Generator is designed for fast exploration and visual ideation. It helps users test graffiti styles, compare creative directions, generate readable lettering, and create urban-inspired visuals. The platform includes free tools, free starter credits for new users, and one-time paid credit packs for users who need more AI generations or higher-resolution output.